Lecture 1: Introduction to CPSC 330
2026–27 · Winter Term 1
Focus on the breath!
🎯 Today’s big questions
AI, ML, DL: What’s the difference?
Learning from examples: How does it work?
Rules, ML, or people: Which should we choose?
Getting started in CPSC 330: What do you need?
CPSC 330 course materials
- Course website: schedules, syllabus, and policies
- Course book: shared course notes
- Today’s reading: Chapter 1: Course Introduction
- Course GitHub repository
🤝 Introductions 🤝
Meet your instructor
- Varada Kolhatkar [ʋəɾəda kɔːlɦəʈkər]
- You can call me Varada, V, or Ada.
- Associate Professor of Teaching in the Department of Computer Science.
- Ph.D. in Computational Linguistics at the University of Toronto.
- I primarily teach machine learning courses in the Master of Data Science (MDS) program.
- Contact information
- Email: kvarada@cs.ubc.ca
- Office: ICCS 237
Meet Eva (a fictitious persona)!

Eva is among one of you. She has some experience in Python programming. She knows machine learning as a buzz word. During her recent internship, she has developed some interest and curiosity in the field. She wants to learn what is it and how to use it. She is a curious person and usually has a lot of questions!
Activity 1
Discuss the following questions with your neighbour.
- What’s your name and major?
- Where have you encountered machine learning?
- What would you like to get out of this course?
- What’s one thing you’re excited or unsure about?
AI in everyday life
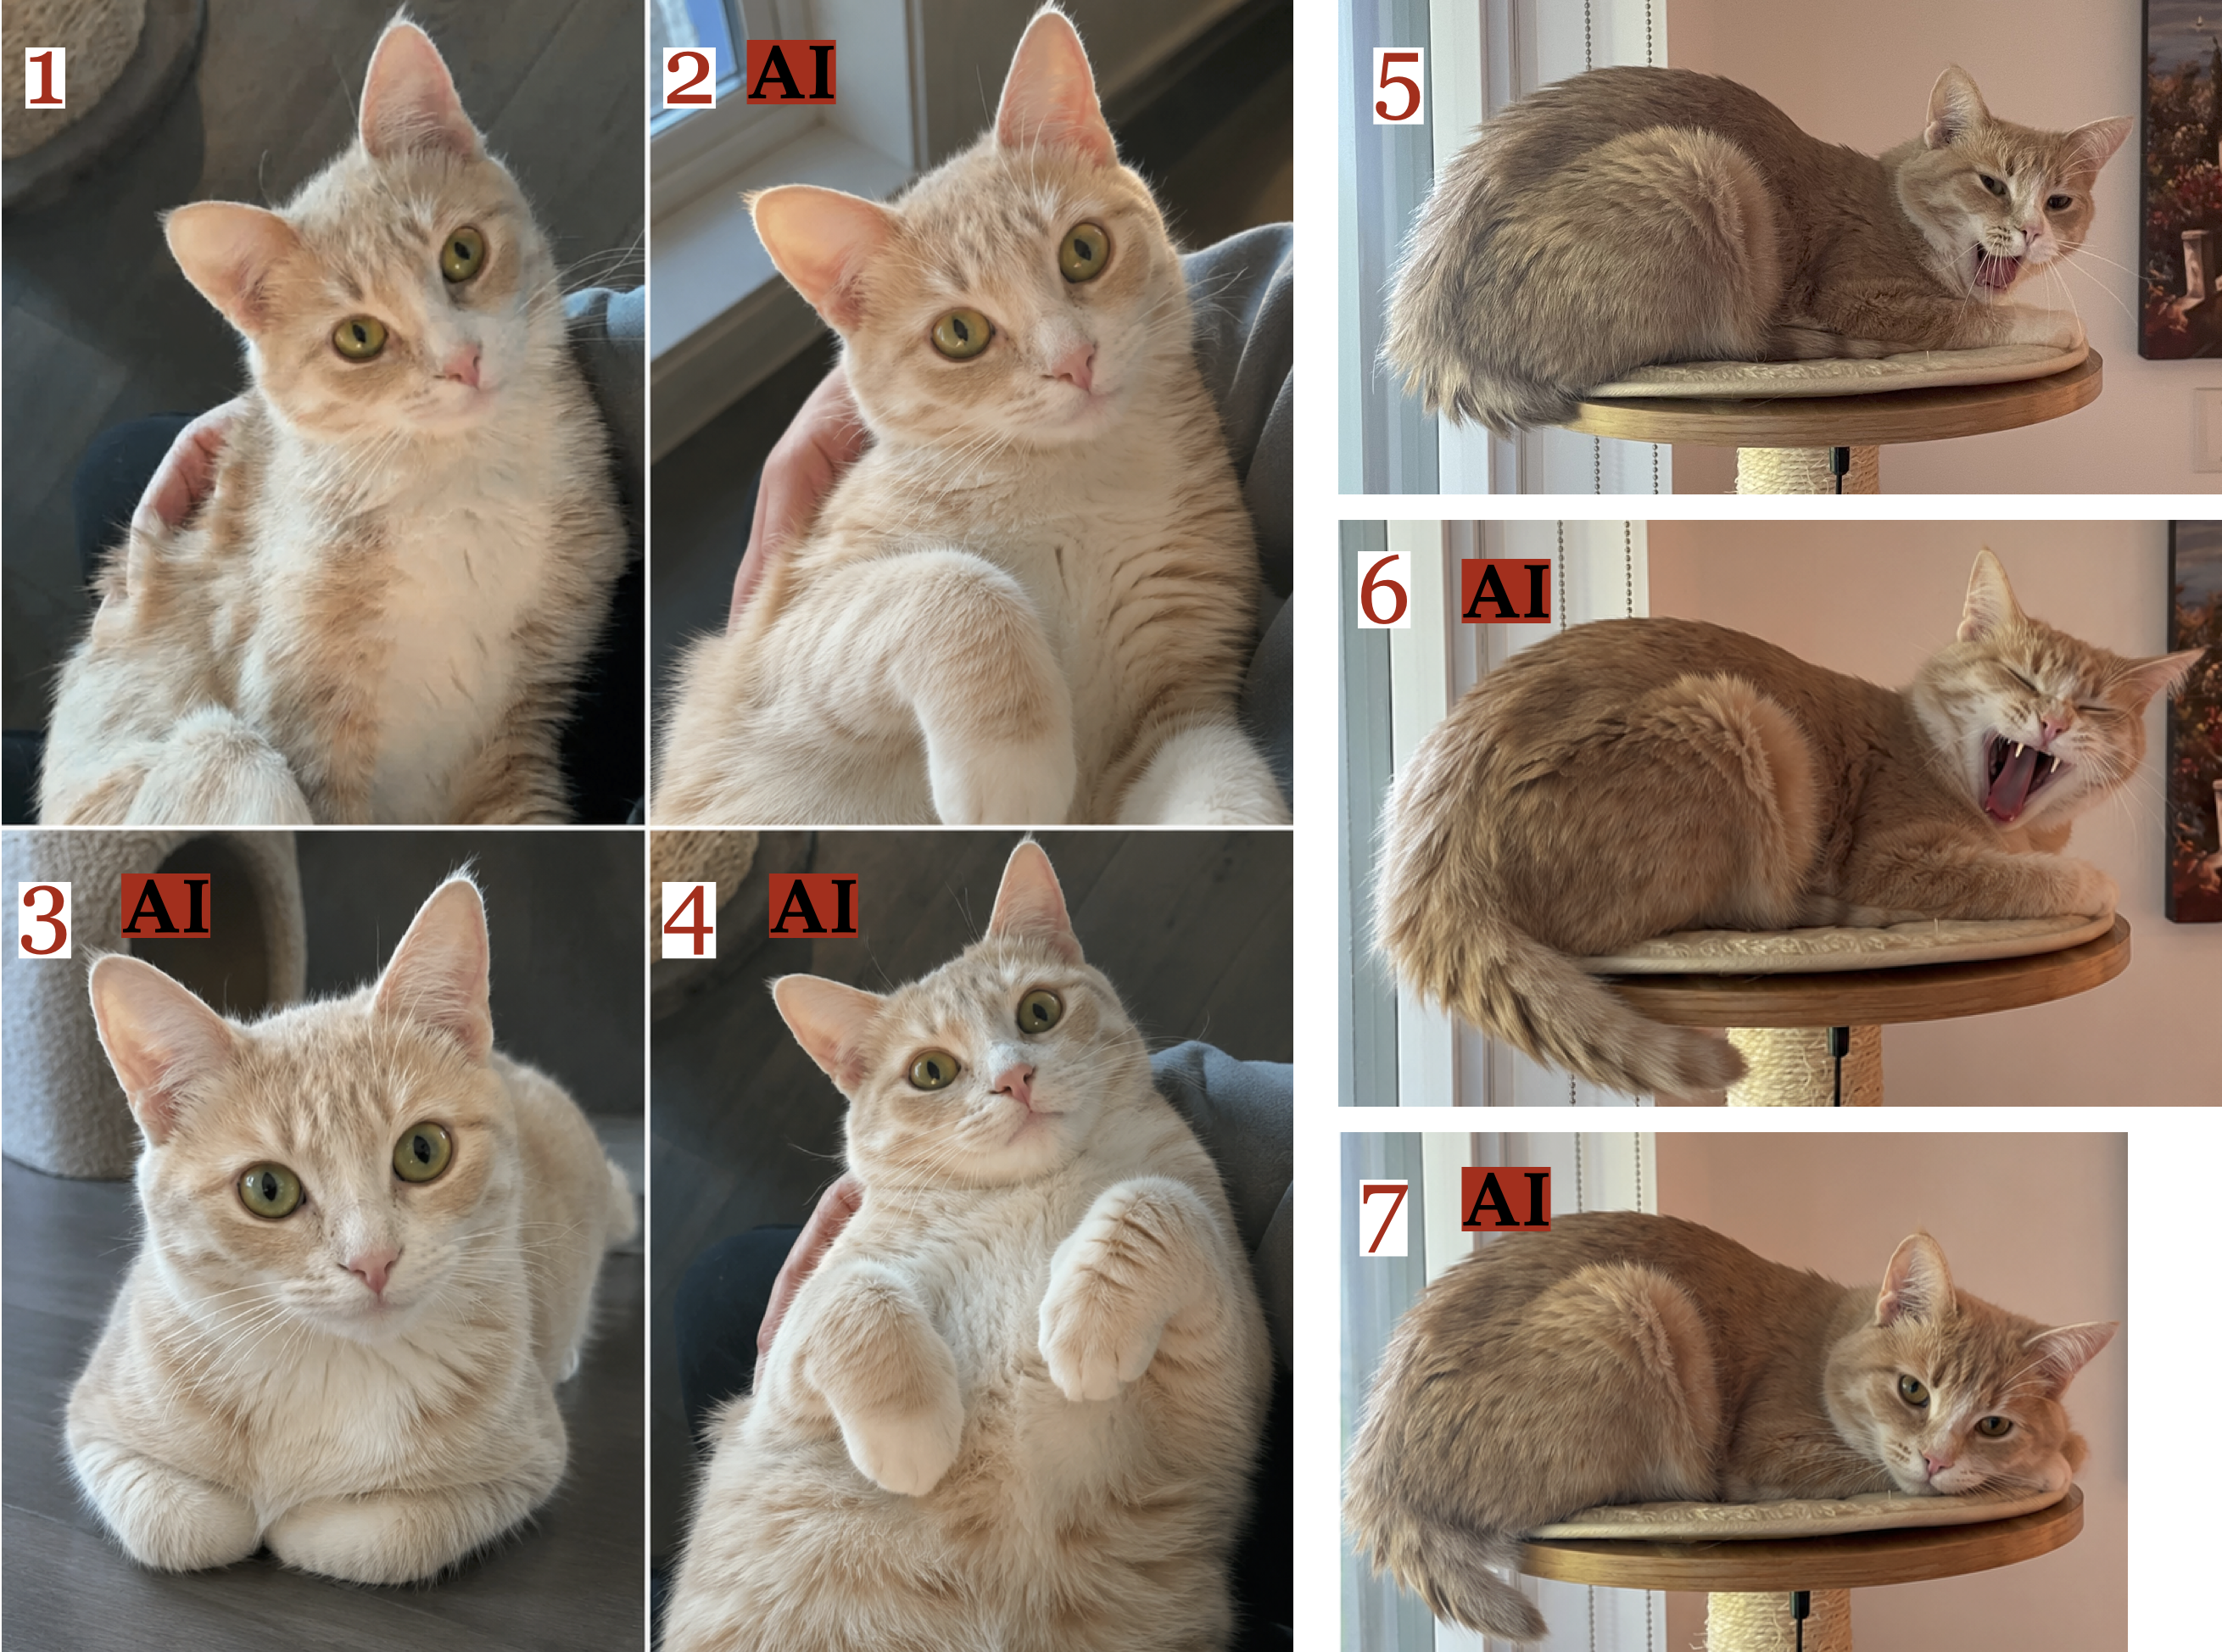
Original vs AI?
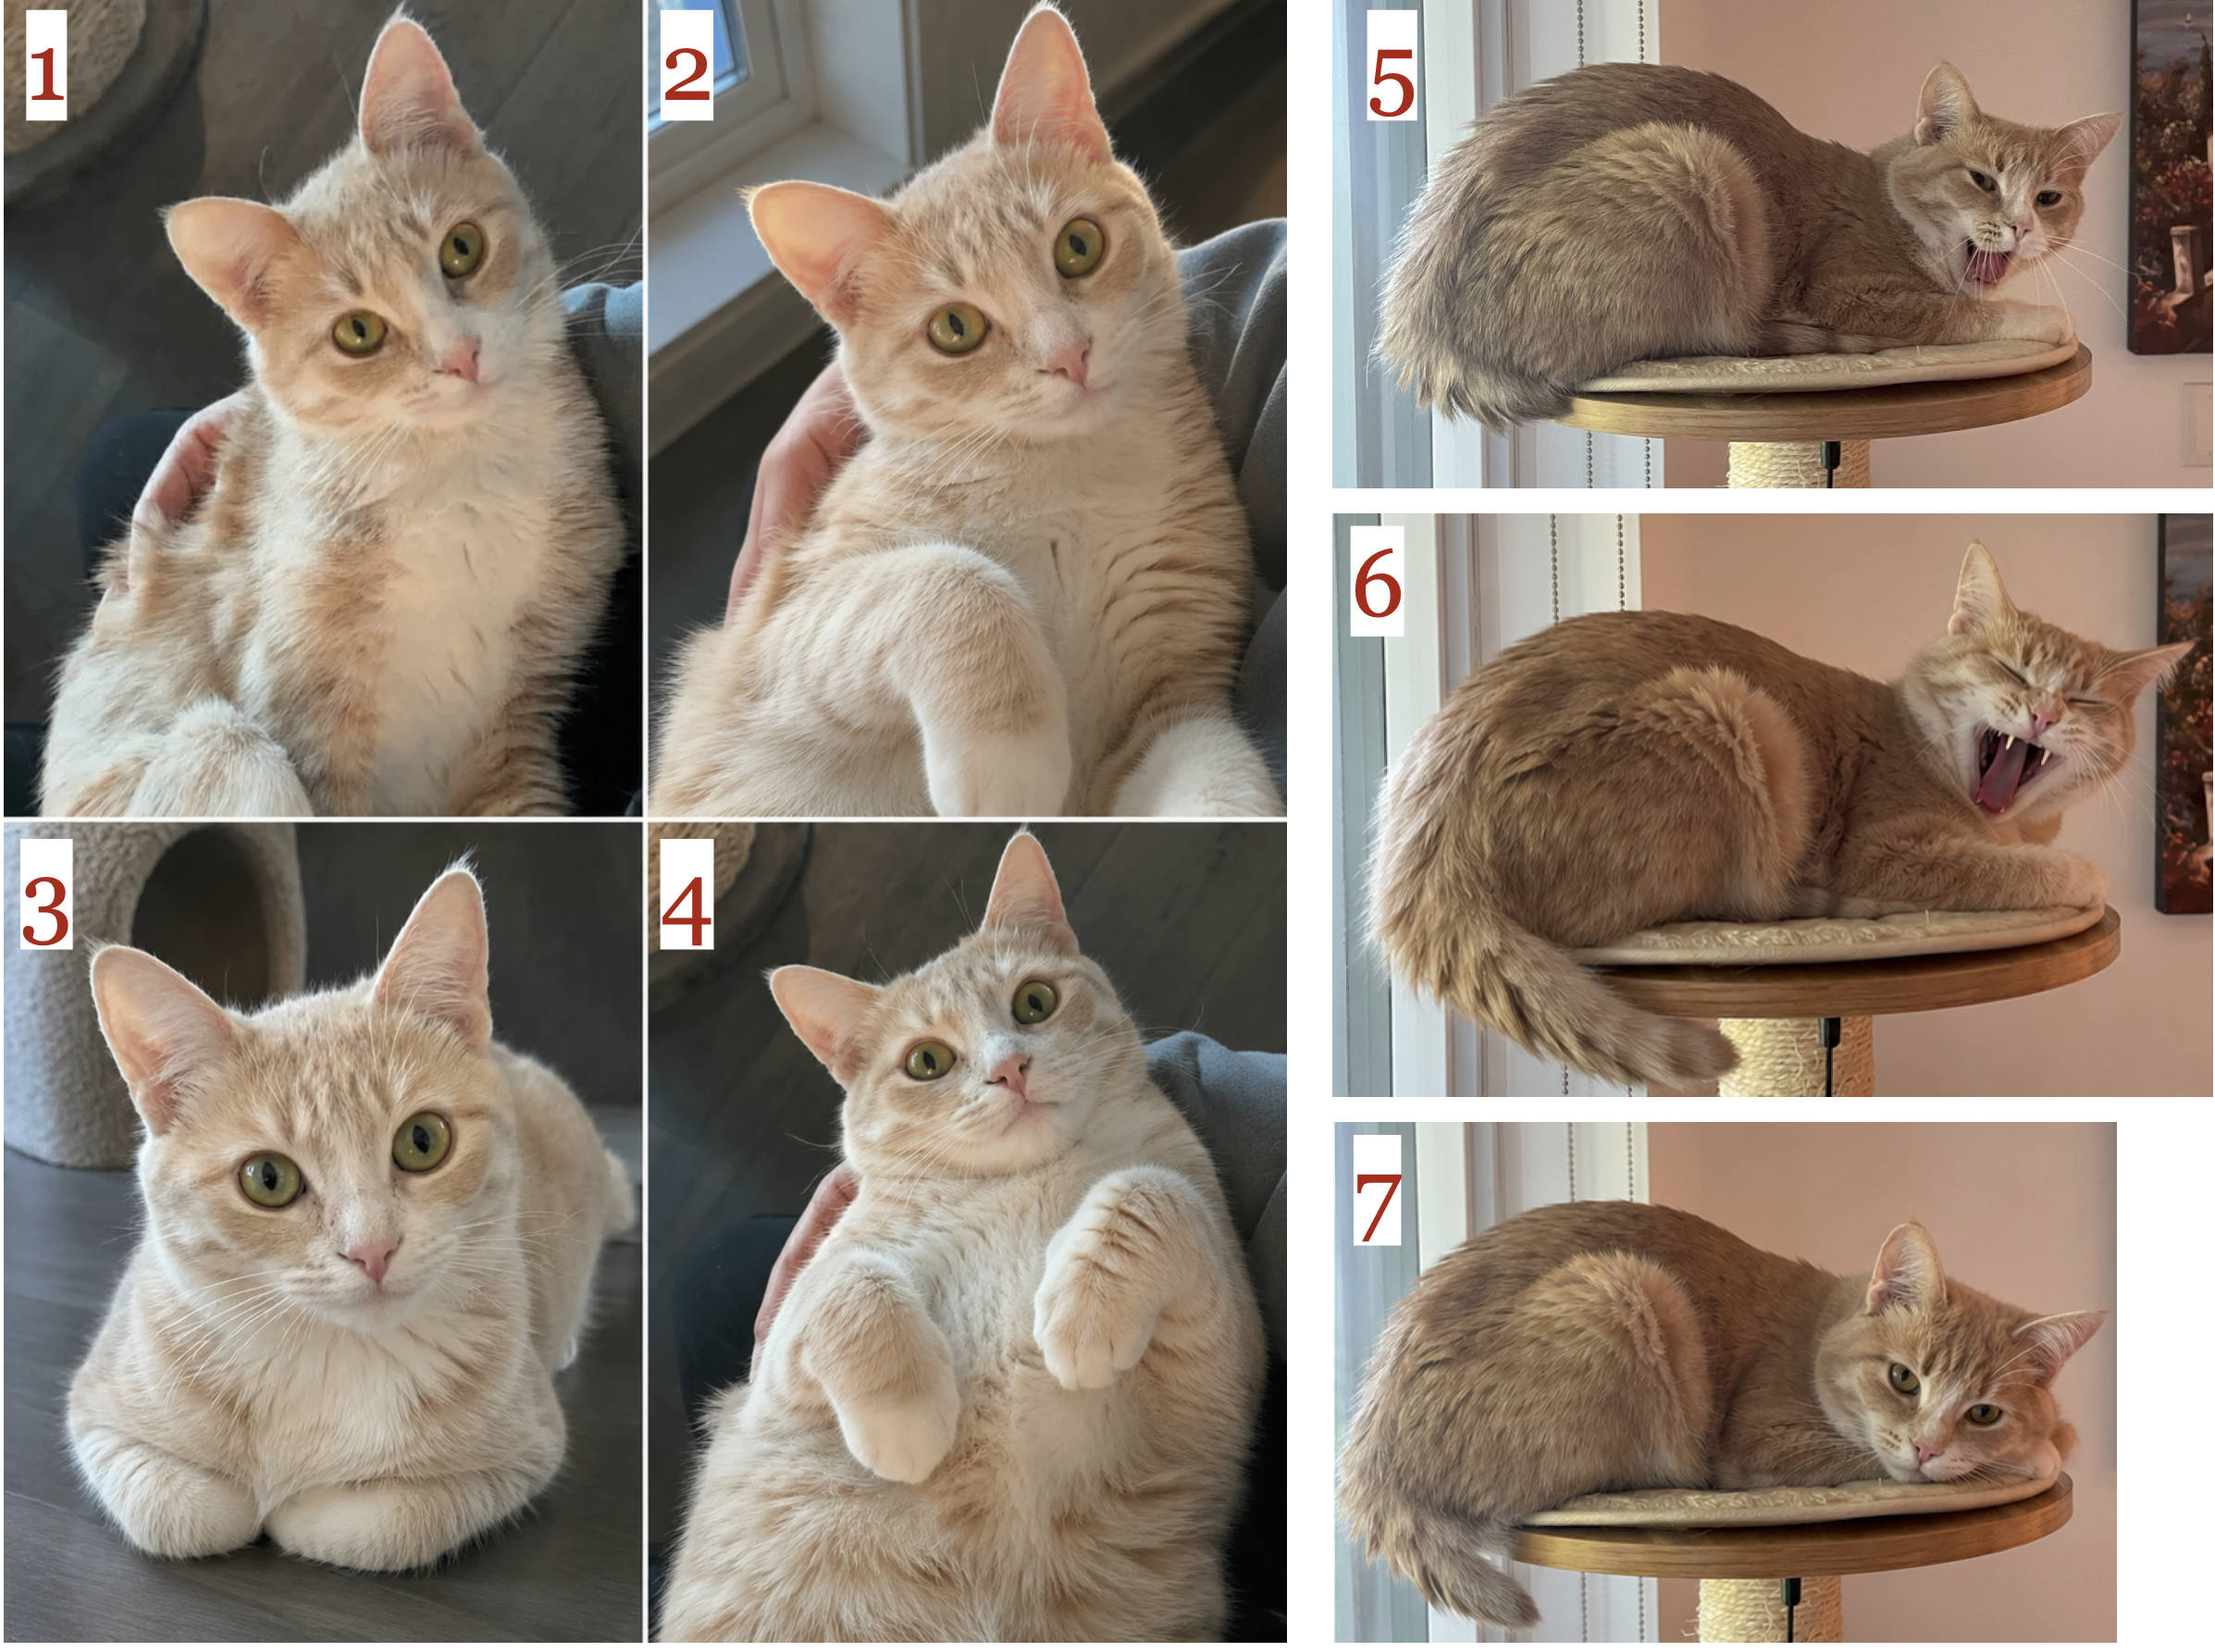
Which cats do you think are AI-generated?
Original vs AI?
How did you decide?
AI in the news
OpenAI reports an AI-generated solution to a major problem about fluid motion.
About one in five students in an Ontario study reported seeking emotional support from AI. The association with emotional problems does not establish causation.
What would you want to know before trusting an AI system in either setting?
Which of these do you think use AI?
- A spam detector 📧
- Autocomplete on your phone 📱
- A basic calculator ➕
- Finding the closest holiday destination by straight-line distance 🛫
- Predicting traffic conditions tomorrow
- Recommending a holiday destination you would enjoy 🛳️
- A chatbot planning your holiday 💬
What makes you call something AI?
AI, ML, and DL
What are AI, ML, and DL?

Our focus: learning from examples and applying what we learn to new cases.
How ML works
Image classification
Searching photos for animals involves image classification. Imagine telling cats and foxes apart. How might we do this with traditional programming? With ML?

| Image ID | Whiskers Present | Ear Size | Face Shape | Fur Color | Eye Shape | Label |
|---|---|---|---|---|---|---|
| 1 | Yes | Large | Round | Mixed | Round | Cat |
| 2 | Yes | Medium | Round | Brown | Almond | Cat |
| 3 | Yes | Large | Pointed | Red | Narrow | Fox |
| 4 | Yes | Large | Pointed | Red | Narrow | Fox |
| 5 | Yes | Small | Round | Mixed | Round | Cat |
| 6 | Yes | Large | Pointed | Red | Narrow | Fox |
| 7 | Yes | Small | Round | Grey | Round | Cat |
| 8 | Yes | Small | Round | Black | Round | Cat |
| 9 | Yes | Large | Pointed | Red | Narrow | Fox |
Who writes the rules?
Traditional programming
We write the rules.
Pointed face + red fur + narrow eyes
↓
Predict fox
Machine learning
We provide labeled examples.
Features + cat/fox labels
↓
Learn a prediction rule
What would happen with either approach if we encountered a fox with white fur?
DL approach: example
- A neural network automatically learns which features to look at (edges → textures → objects).
- No need to even specify face shape or fur colour. It learns relevant features on its own.
Supervised learning: inputs, targets, and predictions
- Inputs (X): observations described by features, such as fur colour and ear size.
- Targets (y): labels or values we want to predict, such as cat or fox.
- Training: learn a model f relating inputs to targets.
- Prediction: use the model to predict targets for unseen examples.

Applications and coding examples
What to look for in the demos
For each example, identify the inputs, the desired output, and where learning happens.
- Spam: learn to predict a category from labeled messages.
- House prices: predict a continuous value.
- Images: reuse a model trained elsewhere.
- Clustering and recommendations: discover groups or patterns in preferences.
Focus on the inputs and outputs. You do not need to understand all the code yet.
Spam classification: labeled examples
- Suppose you are given some data with labeled spam and non-spam messages and you want to predict whether a new message is spam or not spam.
| target | sms |
|---|---|
| spam | LookAtMe!: Thanks for your purchase of a video clip from LookAtMe!, you've been charged 35p. Think you can do better? Why not send a video in a MMSto 32323. |
| ham | Aight, I'll hit you up when I get some cash |
| ham | Don no da:)whats you plan? |
| ham | Going to take your babe out ? |
| ham | No need lar. Jus testing e phone card. Dunno network not gd i thk. Me waiting 4 my sis 2 finish bathing so i can bathe. Dun disturb u liao u cleaning ur room. |
Spam classification: training
Pipeline(steps=[('countvectorizer', CountVectorizer(max_features=5000)),
                ('logisticregression', LogisticRegression(max_iter=5000))])
In a Jupyter environment, please rerun this cell to show the HTML representation or trust the notebook. On GitHub, the HTML representation is unable to render, please try loading this page with nbviewer.org.
Parameters
Fitted attributes
| Name | Type | Value |
|---|---|---|
| classes_ classes_: ndarray of shape (n_classes,) The classes labels. Only exist if the last step of the pipeline is a classifier. |
ndarray[object](2,) | ['ham','spam'] |
Parameters
Fitted attributes
| Name | Type | Value |
|---|---|---|
| fixed_vocabulary_ fixed_vocabulary_: bool True if a fixed vocabulary of term to indices mapping is provided by the user. |
bool | False |
| vocabulary_ vocabulary_: dict A mapping of terms to feature indices. |
dict | {'00': np.int64(0), '000': np.int64(1), '000pes': np.int64(2), '00...06': np.int64(3), ...} |
5000 features
| 00 |
| 000 |
| 000pes |
| 008704050406 |
| 0089 |
| 0121 |
| 01223585236 |
| 01223585334 |
| 0125698789 |
| 02 |
| 0207 |
| 02072069400 |
| 02073162414 |
| 02085076972 |
| 021 |
| 03 |
| 04 |
| 0430 |
| 05 |
| 050703 |
| 0578 |
| 06 |
| 07 |
| 07008009200 |
| 07046744435 |
| 07090201529 |
| 07090298926 |
| 07099833605 |
| 07123456789 |
| 0721072 |
| 07732584351 |
| 07734396839 |
| 07742676969 |
| 07753741225 |
| 0776xxxxxxx |
| 07781482378 |
| 07786200117 |
| 077xxx |
| 078 |
| 07801543489 |
| 07808 |
| 07808247860 |
| 07808726822 |
| 07821230901 |
| 078498 |
| 07880867867 |
| 0789xxxxxxx |
| 07946746291 |
| 0796xxxxxx |
| 07973788240 |
| 07xxxxxxxxx |
| 0800 |
| 08000407165 |
| 08000776320 |
| 08000839402 |
| 08000930705 |
| 08000938767 |
| 08001950382 |
| 08002888812 |
| 08002986030 |
| 08002986906 |
| 08002988890 |
| 08006344447 |
| 0808 |
| 08081263000 |
| 08081560665 |
| 0825 |
| 083 |
| 0844 |
| 08448350055 |
| 08448714184 |
| 0845 |
| 08450542832 |
| 08452810071 |
| 08452810073 |
| 08452810075over18 |
| 0870 |
| 08700435505150p |
| 08700621170150p |
| 08701417012 |
| 08701417012150p |
| 0870241182716 |
| 08702840625 |
| 08707509020 |
| 08708034412 |
| 08709222922 |
| 0871 |
| 08712101358 |
| 08712300220 |
| 08712317606 |
| 08712402050 |
| 08712405020 |
| 08712405022 |
| 08712460324 |
| 0871277810810 |
| 0871277810910p |
| 08714342399 |
| 087147123779am |
| 08714712379 |
| 08714712394 |
| 08714712412 |
| 08715203028 |
| 08715203649 |
| 08715705022 |
| 0871750 |
| 08717898035 |
| 08718720201 |
| 08718726270 |
| 087187262701 |
| 08718726970 |
| 08718726971 |
| 08718726978 |
| 08718727868 |
| 08718727870 |
| 08718727870150ppm |
| 08718730555 |
| 08718730666 |
| 08718738002 |
| 08718738034 |
| 08719180219 |
| 08719180248 |
| 08719181259 |
| 08719181503 |
| 08719181513 |
| 08719839835 |
| 08719899217 |
| 08719899229 |
| 08719899230 |
| 09 |
| 09041940223 |
| 09050000301 |
| 09050000332 |
| 09050000460 |
| 09050000555 |
| 09050000878 |
| 09050000928 |
| 09050001295 |
| 09050001808 |
| 09050002311 |
| 09050003091 |
| 09050005321 |
| 09050090044 |
| 09050280520 |
| 09053750005 |
| 09056242159 |
| 09057039994 |
| 09058091854 |
| 09058094454 |
| 09058094455 |
| 09058094507 |
| 09058094565 |
| 09058094583 |
| 09058094597 |
| 09058094599 |
| 09058095107 |
| 09058095201 |
| 09058097189 |
| 09058098002 |
| 09058099801 |
| 09061104276 |
| 09061209465 |
| 09061213237 |
| 09061221061 |
| 09061221066 |
| 09061701461 |
| 09061701851 |
| 09061701939 |
| 09061702893 |
| 09061743386 |
| 09061743806 |
| 09061743810 |
| 09061743811 |
| 09061744553 |
| 09061749602 |
| 09061790121 |
| 09061790125 |
| 09061790126 |
| 09063440451 |
| 09063442151 |
| 09063458130 |
| 0906346330 |
| 09064011000 |
| 09064012103 |
| 09064012160 |
| 09064015307 |
| 09064017295 |
| 09064017305 |
| 09064018838 |
| 09064019014 |
| 09064019788 |
| 09065069120 |
| 09065069154 |
| 09065171142 |
| 09065174042 |
| 09065394514 |
| 09065394973 |
| 09065989180 |
| 09065989182 |
| 09066350750 |
| 09066358152 |
| 09066358361 |
| 09066361921 |
| 09066362206 |
| 09066362220 |
| 09066362231 |
| 09066364311 |
| 09066364349 |
| 09066364589 |
| 09066368327 |
| 09066368470 |
| 09066368753 |
| 09066380611 |
| 09066382422 |
| 09066612661 |
| 09066649731from |
| 09066660100 |
| 09071512432 |
| 09071512433 |
| 09071517866 |
| 09077818151 |
| 09090204448 |
| 09090900040 |
| 09094646631 |
| 09094646899 |
| 10 |
| 100 |
| 1000 |
| 1000s |
| 100percent |
| 1030 |
| 10am |
| 10k |
| 10p |
| 10ppm |
| 11 |
| 113 |
| 114 |
| 11mths |
| 11pm |
| 12 |
| 121 |
| 123 |
| 1250 |
| 125gift |
| 12hrs |
| 12mths |
| 1327 |
| 14 |
| 145 |
| 1450 |
| 15 |
| 150 |
| 1500 |
| 150p |
| 150p16 |
| 150pm |
| 150ppm |
| 153 |
| 16 |
| 165 |
| 169 |
| 18 |
| 18p |
| 18yrs |
| 1956669 |
| 1hr |
| 1st |
| 1win150ppmx3 |
| 1x150p |
| 20 |
| 200 |
| 2000 |
| 2003 |
| 2004 |
| 2005 |
| 2007 |
| 20p |
| 21 |
| 21870000 |
| 21st |
| 22 |
| 220 |
| 24 |
| 25 |
| 250 |
| 25p |
| 26 |
| 26th |
| 28 |
| 28days |
| 29 |
| 2c |
| 2day |
| 2end |
| 2find |
| 2geva |
| 2go |
| 2gthr |
| 2lands |
| 2marrow |
| 2moro |
| 2morow |
| 2morro |
| 2morrow |
| 2mrw |
| 2nd |
| 2nite |
| 2optout |
| 2p |
| 2rcv |
| 2stop |
| 2stoptxt |
| 2u |
| 2waxsto |
| 2wks |
| 2yr |
| 30 |
| 300 |
| 300603 |
| 300p |
| 3030 |
| 30ish |
| 30pp |
| 31 |
| 3100 |
| 31p |
| 326 |
| 33 |
| 350 |
| 3510i |
| 3650 |
| 36504 |
| 3680 |
| 373 |
| 3aj |
| 3d |
| 3g |
| 3gbp |
| 3hrs |
| 3lp |
| 3mins |
| 3qxj9 |
| 3rd |
| 3ss |
| 3uz |
| 40 |
| 400 |
| 40533 |
| 40gb |
| 41685 |
| 434 |
| 440 |
| 4403ldnw1a7rw18 |
| 447797706009 |
| 45239 |
| 4742 |
| 48 |
| 4882 |
| 48922 |
| 49 |
| 4a |
| 4d |
| 4eva |
| 4few |
| 4fil |
| 4get |
| 4give |
| 4got |
| 4goten |
| 4info |
| 4jx |
| 4msgs |
| 4mths |
| 4qf2 |
| 4t |
| 4th |
| 4the |
| 4thnov |
| 4txt |
| 4u |
| 4utxt |
| 4w |
| 4ward |
| 4wrd |
| 4years |
| 50 |
| 500 |
| 5000 |
| 505060 |
| 50award |
| 50ea |
| 50gbp |
| 50p |
| 50perweeksub |
| 50perwksub |
| 50pmmorefrommobile2bremoved |
| 50ppm |
| 50rcvd |
| 50s |
| 5226 |
| 526 |
| 528 |
| 530 |
| 54 |
| 542 |
| 545 |
| 5digital |
| 5free |
| 5ish |
| 5k |
| 5min |
| 5mls |
| 5p |
| 5pm |
| 5th |
| 5wb |
| 5we |
| 5wkg |
| 60 |
| 600 |
| 6031 |
| 6089 |
| 60p |
| 61 |
| 61200 |
| 61610 |
| 62220cncl |
| 6230 |
| 62468 |
| 62735 |
| 630 |
| 63miles |
| 645 |
| 65 |
| 650 |
| 66 |
| 6669 |
| 674 |
| 67441233 |
| 68866 |
| 69101 |
| 69200 |
| 69669 |
| 69696 |
| 69698 |
| 69866 |
| 69876 |
| 69888 |
| 69888nyt |
| 69911 |
| 69969 |
| 69988 |
| 6days |
| 6hl |
| 6hrs |
| 6ish |
| 6missed |
| 6months |
| 6ph |
| 6pm |
| 6th |
| 6times |
| 6wu |
| 6zf |
| 700 |
| 7250 |
| 7250i |
| 730 |
| 731 |
| 74355 |
| 75 |
| 750 |
| 7548 |
| 75max |
| 762 |
| 7634 |
| 7684 |
| 77 |
| 7732584351 |
| 78 |
| 786 |
| 7876150ppm |
| 79 |
| 7am |
| 7cfca1a |
| 7ish |
| 7mp |
| 7oz |
| 7pm |
| 7th |
| 7ws |
| 7zs |
| 80 |
| 800 |
| 8000930705 |
| 80062 |
| 8007 |
| 80082 |
| 80086 |
| 80122300p |
| 80155 |
| 80160 |
| 80182 |
| 8027 |
| 80488 |
| 80608 |
| 8077 |
| 80878 |
| 81010 |
| 81151 |
| 81303 |
| 81618 |
| 82050 |
| 820554ad0a1705572711 |
| 82242 |
| 82277 |
| 82468 |
| 83021 |
| 83039 |
| 83049 |
| 83110 |
| 83118 |
| 83222 |
| 83332 |
| 83338 |
| 83355 |
| 83370 |
| 83383 |
| 83435 |
| 83600 |
| 83738 |
| 84 |
| 84025 |
| 84122 |
| 84128 |
| 84199 |
| 85 |
| 850 |
| 85023 |
| 85069 |
| 85222 |
| 85233 |
| 8552 |
| 85555 |
| 86021 |
| 861 |
| 864233 |
| 86688 |
| 86888 |
| 87021 |
| 87066 |
| 87070 |
| 87077 |
| 87121 |
| 87131 |
| 8714714 |
| 872 |
| 87239 |
| 87575 |
| 8800 |
| 88039 |
| 88066 |
| 88088 |
| 88222 |
| 88600 |
| 88800 |
| 8883 |
| 88877 |
| 88888 |
| 89034 |
| 89070 |
| 89080 |
| 89105 |
| 89545 |
| 89555 |
| 89693 |
| 8p |
| 8pm |
| 8th |
| 8wp |
| 900 |
| 910 |
| 930 |
| 99 |
| 9ae |
| 9am |
| 9ja |
| 9pm |
| 9t |
| ____ |
| aah |
| aathi |
| abi |
| ability |
| abiola |
| abj |
| able |
| about |
| absolutly |
| abt |
| abta |
| ac |
| academic |
| acc |
| accept |
| access |
| accident |
| accidentally |
| accordingly |
| account |
| accounts |
| ache |
| aco |
| across |
| acted |
| action |
| activate |
| activities |
| actor |
| actual |
| actually |
| ad |
| adam |
| add |
| addamsfa |
| added |
| addicted |
| addie |
| address |
| admin |
| administrator |
| admirer |
| admit |
| adore |
| ads |
| adult |
| advance |
| adventure |
| advice |
| advise |
| aeronautics |
| aeroplane |
| affair |
| affairs |
| affection |
| afraid |
| aft |
| after |
| afternoon |
| aftr |
| ag |
| again |
| against |
| age |
| age16 |
| age23 |
| ages |
| ago |
| ah |
| aha |
| ahead |
| ahmad |
| aight |
| ain |
| aint |
| air |
| airport |
| airtel |
| aiya |
| aiyah |
| aiyar |
| aiyo |
| aka |
| al |
| album |
| alcohol |
| alert |
| alex |
| alfie |
| algarve |
| ali |
| alive |
| all |
| allah |
| allow |
| allowed |
| almost |
| alone |
| along |
| already |
| alright |
| alrite |
| also |
| always |
| alwys |
| am |
| amazing |
| american |
| among |
| amount |
| amp |
| amt |
| amused |
| amy |
| an |
| and |
| andros |
| angry |
| anna |
| annie |
| announcement |
| annoying |
| anot |
| another |
| ans |
| ansr |
| answer |
| answering |
| answers |
| anthony |
| anti |
| any |
| anybody |
| anymore |
| anyone |
| anythin |
| anything |
| anytime |
| anyway |
| anyways |
| anywhere |
| apart |
| apartment |
| apo |
| apologise |
| app |
| apparently |
| applebees |
| apply |
| appointment |
| appreciate |
| appreciated |
| apps |
| appt |
| april |
| aproach |
| ar |
| arcade |
| ard |
| are |
| area |
| aren |
| arent |
| argh |
| argue |
| argument |
| arm |
| armand |
| arms |
| arng |
| around |
| arrange |
| arrested |
| arrive |
| arsenal |
| art |
| arts |
| arun |
| as |
| asap |
| ashley |
| ask |
| askd |
| asked |
| askin |
| asking |
| asks |
| asleep |
| asp |
| ass |
| assume |
| at |
| ate |
| atlanta |
| atlast |
| atm |
| attached |
| attempt |
| attend |
| auction |
| audition |
| audrey |
| august |
| aunt |
| aunty |
| auto |
| available |
| avatar |
| ave |
| avent |
| avoiding |
| await |
| awaiting |
| awake |
| award |
| awarded |
| away |
| awesome |
| aww |
| ayn |
| b4 |
| b4190604 |
| b4280703 |
| babe |
| babes |
| babies |
| baby |
| back |
| bad |
| bag |
| bags |
| bahamas |
| bak |
| balance |
| bank |
| banks |
| bar |
| barely |
| base |
| basic |
| basically |
| bat |
| batch |
| bath |
| bathe |
| bathing |
| battery |
| bay |
| bb |
| bbd |
| bc |
| bck |
| bcm1896wc1n3xx |
| bcm4284 |
| bcoz |
| bcums |
| bday |
| be |
| bear |
| bears |
| beautiful |
| beauty |
| bec |
| because |
| become |
| becomes |
| becoz |
| bed |
| bedrm |
| bedroom |
| been |
| beer |
| befor |
| before |
| beg |
| begging |
| begin |
| behave |
| behind |
| bein |
| being |
| believe |
| belive |
| bell |
| belly |
| belovd |
| ben |
| beneath |
| benefits |
| best |
| best1 |
| bet |
| better |
| between |
| beware |
| beyond |
| bf |
| bhaji |
| bid |
| big |
| bigger |
| biggest |
| bill |
| billed |
| billion |
| bills |
| bin |
| biola |
| bird |
| birds |
| birla |
| birth |
| birthdate |
| birthday |
| bishan |
| bit |
| bitch |
| bite |
| biz |
| black |
| blackberry |
| blah |
| blake |
| blame |
| blank |
| bleh |
| bless |
| blessed |
| blessing |
| blessings |
| blind |
| block |
| bloke |
| blonde |
| blood |
| bloody |
| bloomberg |
| blow |
| blu |
| blue |
| bluetooth |
| bluff |
| blur |
| bmw |
| boat |
| body |
| bold |
| bonus |
| boo |
| book |
| booked |
| booking |
| books |
| boost |
| booty |
| bootydelious |
| bored |
| borin |
| boring |
| born |
| borrow |
| boss |
| boston |
| both |
| bother |
| bottle |
| bottom |
| bought |
| bout |
| bowl |
| box |
| box177 |
| box326 |
| box334sk38ch |
| box385 |
| box39822 |
| box95qu |
| box97n7qp |
| boy |
| boye |
| boys |
| boytoy |
| brah |
| brain |
| brand |
| bray |
| bread |
| break |
| breath |
| breathe |
| brief |
| bright |
| brilliant |
| bring |
| bringing |
| brings |
| bristol |
| british |
| britney |
| broad |
| broke |
| broken |
| brothas |
| brother |
| brought |
| bruce |
| bruv |
| bslvyl |
| bstfrnd |
| bt |
| btw |
| bucks |
| bud |
| budget |
| buff |
| buffet |
| bugis |
| building |
| bulbs |
| buns |
| burger |
| burning |
| burns |
| bus |
| buses |
| business |
| busy |
| but |
| butt |
| buy |
| buying |
| buzz |
| bx420 |
| by |
| bye |
| båõday |
| c52 |
| cabin |
| cafe |
| cake |
| cal |
| calculation |
| cali |
| calicut |
| california |
| call |
| call09050000327 |
| call2optout |
| callback |
| callcost |
| calld |
| called |
| caller |
| callers |
| callertune |
| callfreefone |
| callin |
| calling |
| calls |
| callså |
| calm |
| cam |
| camcorder |
| came |
| camera |
| campus |
| can |
| canal |
| canary |
| cancel |
| cancer |
| cann |
| cannot |
| cant |
| capital |
| cappuccino |
| captain |
| car |
| card |
| cardiff |
| care |
| cared |
| career |
| careers |
| careful |
| carefully |
| caring |
| carlos |
| caroline |
| carry |
| cars |
| cartoon |
| case |
| cash |
| cashbin |
| cashto |
| castor |
| cat |
| catch |
| catching |
| caught |
| cause |
| causing |
| cbe |
| cc |
| cd |
| cdgt |
| cds |
| celeb |
| celebrate |
| celebration |
| cell |
| center |
| centre |
| certainly |
| cha |
| chain |
| challenge |
| chance |
| chances |
| change |
| changed |
| changes |
| channel |
| character |
| charge |
| charged |
| charges |
| charity |
| charles |
| chart |
| chase |
| chasing |
| chat |
| chatting |
| cheap |
| cheaper |
| cheat |
| cheating |
| chechi |
| check |
| checked |
| checking |
| cheer |
| cheers |
| cheese |
| chennai |
| cherish |
| chicken |
| chikku |
| child |
| childish |
| children |
| chill |
| chillin |
| china |
| chinese |
| chocolate |
| choice |
| choose |
| chosen |
| christ |
| christmas |
| church |
| cine |
| cinema |
| citizen |
| city |
| claim |
| claims |
| claire |
| clark |
| class |
| classes |
| cld |
| clean |
| cleaning |
| clear |
| cleared |
| clearing |
| clearly |
| clever |
| click |
| clock |
| clos1 |
| close |
| closed |
| closer |
| closes |
| club |
| clubmoby |
| cm |
| cm2 |
| cme |
| cn |
| cnn |
| co |
| coast |
| coat |
| cochin |
| cock |
| code |
| coffee |
| coin |
| coins |
| cold |
| colleagues |
| collect |
| collected |
| collecting |
| collection |
| college |
| color |
| colour |
| colours |
| com |
| com1win150ppmx3age16 |
| combine |
| come |
| comedy |
| comes |
| comin |
| coming |
| commercial |
| common |
| community |
| comp |
| company |
| compare |
| competition |
| complete |
| completed |
| completely |
| complimentary |
| computer |
| comuk |
| concentrate |
| concert |
| condition |
| conditions |
| conducts |
| confidence |
| confirm |
| confirmd |
| confirmed |
| conform |
| confused |
| confuses |
| congrats |
| congratulations |
| connect |
| connection |
| consider |
| considering |
| constant |
| constantly |
| contact |
| contacted |
| contacts |
| content |
| contents |
| continue |
| contract |
| control |
| convey |
| convinced |
| convincing |
| cook |
| cooked |
| cookies |
| cooking |
| cool |
| coping |
| copy |
| cornwall |
| correct |
| correction |
| cos |
| cost |
| costa |
| costing |
| costs |
| costå |
| could |
| couldn |
| count |
| country |
| couple |
| courage |
| course |
| cousin |
| cover |
| covers |
| coz |
| cr01327bt |
| cr9 |
| crab |
| crack |
| cramps |
| crap |
| crash |
| crave |
| craziest |
| crazy |
| cream |
| created |
| credit |
| credits |
| creepy |
| cricketer |
| crore |
| cross |
| croydon |
| cruise |
| cry |
| cs |
| csbcm4235wc1n3xx |
| csh11 |
| cud |
| cuddle |
| cuddling |
| cum |
| cup |
| current |
| currently |
| cust |
| custcare |
| custom |
| customer |
| customers |
| cut |
| cute |
| cutefrnd |
| cutting |
| cuz |
| cw25wx |
| da |
| dad |
| daddy |
| dai |
| daily |
| damn |
| dan |
| dancing |
| dare |
| dark |
| darlin |
| darling |
| darren |
| dat |
| date |
| datebox1282essexcm61xn |
| dates |
| dating |
| dave |
| day |
| days |
| dbuk |
| de |
| dead |
| deal |
| dear |
| dear1 |
| dearer |
| dearly |
| death |
| december |
| decide |
| decided |
| deciding |
| decimal |
| decision |
| decisions |
| dedicate |
| dedicated |
| deep |
| deepak |
| deeraj |
| def |
| defeat |
| definitely |
| del |
| delay |
| delete |
| deleted |
| delhi |
| deliver |
| delivered |
| deliveredtomorrow |
| delivery |
| dem |
| demand |
| den |
| denis |
| department |
| depends |
| depressed |
| derek |
| desires |
| desparate |
| desperate |
| despite |
| details |
| detroit |
| deus |
| develop |
| devouring |
| dey |
| dhoni |
| di |
| dial |
| diamonds |
| dick |
| dictionary |
| did |
| didn |
| didnt |
| didnåõt |
| die |
| died |
| diet |
| diff |
| differ |
| difference |
| different |
| difficult |
| dificult |
| digital |
| dignity |
| dime |
| din |
| ding |
| dining |
| dinner |
| dint |
| direct |
| directly |
| dirty |
| dis |
| disclose |
| disconnect |
| discount |
| discreet |
| discuss |
| discussed |
| dislikes |
| display |
| distance |
| disturb |
| disturbing |
| division |
| divorce |
| diwali |
| dload |
| dnt |
| do |
| dobby |
| doc |
| docs |
| doctor |
| does |
| doesn |
| doesnt |
| dog |
| dogging |
| doggy |
| doin |
| doing |
| dokey |
| dollars |
| don |
| donate |
| done |
| donno |
| dont |
| donåõt |
| door |
| doors |
| dorm |
| dot |
| double |
| doubt |
| down |
| download |
| downloads |
| dr |
| dracula |
| draw |
| dream |
| dreams |
| dress |
| dressed |
| dresser |
| drink |
| drinkin |
| drinking |
| drinks |
| drive |
| driver |
| drivin |
| driving |
| drms |
| drop |
| dropped |
| drove |
| drpd |
| drug |
| drugs |
| drunk |
| drunken |
| dry |
| dsn |
| dt |
| dubsack |
| duchess |
| dude |
| due |
| dumb |
| dun |
| dunno |
| durban |
| during |
| dvd |
| each |
| earlier |
| early |
| earth |
| easier |
| easily |
| east |
| eastenders |
| easter |
| easy |
| eat |
| eaten |
| eatin |
| eating |
| ebay |
| ec2a |
| edge |
| edu |
| educational |
| ee |
| eek |
| eerie |
| effect |
| effects |
| eg |
| egg |
| eggs |
| eh |
| eight |
| eighth |
| eire |
| either |
| ela |
| elaine |
| else |
| elsewhere |
| em |
| embarassed |
| empty |
| en |
| end |
| ended |
| ending |
| ends |
| enemy |
| energy |
| eng |
| engin |
| england |
| english |
| enjoy |
| enjoyed |
| enough |
| enter |
| entered |
| entitled |
| entry |
| entry41 |
| enuff |
| envelope |
| environment |
| epsilon |
| er |
| ericsson |
| erm |
| error |
| escape |
| ese |
| especially |
| esplanade |
| essential |
| eta |
| etc |
| euro |
| euro2004 |
| eurodisinc |
| europe |
| eve |
| even |
| evening |
| evenings |
| event |
| ever |
| every |
| everybody |
| everyday |
| everyone |
| everything |
| everywhere |
| evn |
| evng |
| evr |
| evrey |
| evry |
| evrydy |
| ex |
| exact |
| exactly |
| exam |
| exams |
| excellent |
| except |
| exciting |
| excuse |
| excuses |
| executive |
| exeter |
| exhaust |
| exhausted |
| exmpel |
| exorcist |
| expect |
| expecting |
| expensive |
| experience |
| expires |
| explain |
| explicit |
| explosive |
| express |
| expression |
| expressoffer |
| extra |
| ey |
| eye |
| eyes |
| fa |
| fab |
| face |
| fact |
| faggy |
| failed |
| fails |
| fair |
| faith |
| fall |
| falling |
| falls |
| family |
| fan |
| fancies |
| fancy |
| fantasies |
| fantastic |
| fantasy |
| far |
| farm |
| fast |
| faster |
| fastest |
| fat |
| father |
| fathima |
| fault |
| fav |
| fave |
| favor |
| favorite |
| favour |
| favourite |
| fb |
| fear |
| feb |
| february |
| feel |
| feeling |
| feels |
| fees |
| feet |
| fell |
| felt |
| female |
| fetch |
| fever |
| few |
| field |
| fifteen |
| fight |
| fighting |
| fightng |
| fights |
| figure |
| figures |
| file |
| files |
| fill |
| filled |
| filling |
| fills |
| film |
| films |
| filthy |
| final |
| finally |
| finance |
| find |
| fine |
| fingers |
| finish |
| finished |
| finishes |
| fire |
| first |
| fish |
| fit |
| five |
| fix |
| fixed |
| fixedline |
| flag |
| flaked |
| flame |
| flash |
| flat |
| flies |
| flight |
| flights |
| flip |
| flirt |
| flirting |
| floor |
| flower |
| flowing |
| fml |
| fo |
| foley |
| follow |
| followed |
| following |
| fone |
| food |
| fool |
| foot |
| football |
| footprints |
| for |
| force |
| foreign |
| forever |
| forevr |
| forget |
| forgets |
| forgiven |
| forgot |
| forgotten |
| form |
| format |
| forms |
| forum |
| forward |
| forwarded |
| found |
| four |
| fr |
| fran |
| frauds |
| freak |
| free |
| free2day |
| freedom |
| freefone |
| freemsg |
| freephone |
| freezing |
| fren |
| frens |
| fret |
| fri |
| friday |
| friend |
| friends |
| friendship |
| fringe |
| frm |
| frnd |
| frnds |
| frndship |
| frog |
| from |
| fromm |
| front |
| frying |
| fuck |
| fuckin |
| fucking |
| fujitsu |
| ful |
| full |
| fullonsms |
| fun |
| funeral |
| funk |
| funky |
| funny |
| further |
| future |
| fyi |
| g696ga |
| gain |
| gal |
| galileo |
| gals |
| game |
| games |
| ganesh |
| gang |
| gap |
| gaps |
| garage |
| garbage |
| garden |
| gardener |
| gary |
| gas |
| gautham |
| gave |
| gay |
| gaytextbuddy |
| gbp |
| gd |
| ge |
| gee |
| geeee |
| geeeee |
| gender |
| generally |
| genius |
| gent |
| gentle |
| gentleman |
| gently |
| genuine |
| george |
| germany |
| get |
| gets |
| getstop |
| gettin |
| getting |
| getzed |
| ghost |
| gift |
| gimme |
| girl |
| girlfrnd |
| girls |
| gist |
| giv |
| give |
| gives |
| giving |
| glad |
| gm |
| gn |
| go |
| go2 |
| goal |
| goals |
| god |
| gods |
| goes |
| goin |
| going |
| goldviking |
| gona |
| gone |
| gonna |
| good |
| goodfriend |
| goodmorning |
| goodnight |
| goodnite |
| goodo |
| gorgeous |
| gossip |
| got |
| goto |
| gotta |
| govt |
| gpu |
| gr8 |
| gr8prizes |
| grahmbell |
| gram |
| grand |
| granite |
| gravity |
| great |
| greatest |
| green |
| greet |
| greetings |
| grins |
| ground |
| group |
| grow |
| growing |
| gt |
| guaranteed |
| gud |
| gudnite |
| guess |
| guide |
| guilty |
| guy |
| guys |
| gv |
| gving |
| gym |
| ha |
| habit |
| had |
| haf |
| haha |
| hahaha |
| hai |
| hair |
| haiz |
| half |
| hallaq |
| halloween |
| ham |
| hand |
| handed |
| handle |
| hands |
| handset |
| hanging |
| happen |
| happend |
| happened |
| happening |
| happens |
| happily |
| happiness |
| happy |
| hard |
| hardcore |
| hardly |
| harry |
| has |
| hasn |
| hate |
| hav |
| have |
| haven |
| havent |
| havenåõt |
| havin |
| having |
| havnt |
| he |
| head |
| headache |
| headin |
| heading |
| heads |
| hear |
| heard |
| heart |
| heater |
| heavy |
| hee |
| height |
| held |
| hell |
| hella |
| hello |
| help |
| help08718728876 |
| hence |
| henry |
| her |
| here |
| herself |
| hes |
| hex |
| hey |
| hg |
| hi |
| hide |
| high |
| hill |
| him |
| hint |
| hip |
| his |
| history |
| hit |
| hiya |
| hl |
| hlp |
| hm |
| hmm |
| hmmm |
| hmv |
| ho |
| hockey |
| hold |
| holder |
| holding |
| holiday |
| holla |
| hols |
| home |
| homeowners |
| hon |
| honey |
| honeybee |
| hook |
| hop |
| hope |
| hoped |
| hopefully |
| hoping |
| hor |
| horny |
| horo |
| horrible |
| hospital |
| hospitals |
| hostel |
| hot |
| hotel |
| hotels |
| hour |
| hours |
| house |
| housewives |
| how |
| howard |
| however |
| hows |
| howz |
| hppnss |
| hr |
| hrishi |
| hrs |
| hsbc |
| http |
| hubby |
| hug |
| huge |
| hugs |
| huh |
| hun |
| hungry |
| hunny |
| hurried |
| hurry |
| hurt |
| hurting |
| hurts |
| husband |
| hv |
| hw |
| hyde |
| iam |
| ias |
| ibh |
| ibhltd |
| ibiza |
| ibn |
| ic |
| ice |
| icicibank |
| id |
| idea |
| ideal |
| ideas |
| identifier |
| idiot |
| idk |
| if |
| ignore |
| ikea |
| il |
| ill |
| im |
| imagine |
| imma |
| immediately |
| imp |
| important |
| impossible |
| improved |
| in |
| in2 |
| inc |
| inch |
| inches |
| incident |
| include |
| including |
| inclusive |
| inconsiderate |
| incredible |
| increments |
| indeed |
| index |
| india |
| indian |
| indians |
| indicate |
| individual |
| indyarocks |
| infernal |
| info |
| inform |
| information |
| informed |
| infront |
| ing |
| innings |
| innocent |
| inr |
| insha |
| inshah |
| inside |
| instantly |
| instead |
| instituitions |
| instructions |
| insurance |
| intelligent |
| interest |
| interested |
| interesting |
| interflora |
| internet |
| interview |
| into |
| intro |
| invest |
| invite |
| invited |
| inviting |
| invnted |
| iouri |
| ip4 |
| ipad |
| ipod |
| iq |
| irritates |
| irritating |
| is |
| iscoming |
| ish |
| island |
| islands |
| isn |
| isnt |
| issue |
| issues |
| it |
| italian |
| itcould |
| items |
| its |
| itself |
| itz |
| itåõs |
| ive |
| iz |
| izzit |
| iåõm |
| jacket |
| jackpot |
| jada |
| james |
| jamster |
| jan |
| jane |
| january |
| japanese |
| jas |
| jason |
| java |
| jay |
| jaya |
| jazz |
| jd |
| jealous |
| jeans |
| jen |
| jenny |
| jerry |
| jess |
| jesus |
| jiayin |
| jiu |
| joanna |
| job |
| jobs |
| jogging |
| john |
| join |
| joined |
| joining |
| joke |
| jokes |
| jokin |
| joking |
| jolly |
| jolt |
| jordan |
| journey |
| joy |
| jsco |
| jst |
| jstfrnd |
| jsut |
| juan |
| juicy |
| july |
| june |
| jus |
| just |
| juz |
| k52 |
| kadeem |
| kaiez |
| kallis |
| kano |
| kappa |
| karaoke |
| kate |
| kavalan |
| kb |
| ke |
| keep |
| keeping |
| keeps |
| kegger |
| kept |
| kerala |
| keralacircle |
| kettoda |
| key |
| keys |
| kg |
| kick |
| kicks |
| kid |
| kids |
| kidz |
| killed |
| killing |
| kills |
| kind |
| kinda |
| kindly |
| king |
| kiosk |
| kiss |
| kisses |
| knackered |
| knew |
| knock |
| know |
| knowing |
| knows |
| knw |
| konw |
| kothi |
| kr |
| kusruthi |
| l8r |
| la |
| lab |
| lacs |
| ladies |
| lady |
| lag |
| laid |
| land |
| landline |
| landlines |
| lane |
| langport |
| language |
| laptop |
| lar |
| largest |
| last |
| late |
| lately |
| later |
| latest |
| latr |
| laugh |
| laughed |
| laughing |
| laundry |
| law |
| lays |
| lazy |
| lccltd |
| ldew |
| ldn |
| ldnw15h |
| le |
| lead |
| learn |
| least |
| leave |
| leaves |
| leaving |
| lect |
| lecture |
| left |
| legal |
| legs |
| leh |
| lei |
| lemme |
| leona |
| less |
| lesson |
| lessons |
| let |
| lets |
| letter |
| letters |
| lf56 |
| liao |
| lib |
| library |
| lick |
| lido |
| lie |
| lies |
| life |
| lifetime |
| lifpartnr |
| lift |
| light |
| lik |
| like |
| liked |
| likely |
| likes |
| lil |
| lily |
| line |
| linerental |
| lines |
| link |
| lion |
| lionm |
| lionp |
| lions |
| lip |
| list |
| listen |
| listening |
| literally |
| little |
| live |
| lived |
| liverpool |
| lives |
| living |
| ll |
| lmao |
| lo |
| loads |
| loan |
| local |
| location |
| locations |
| lock |
| log |
| login |
| logo |
| logos |
| lol |
| london |
| lonely |
| long |
| longer |
| look |
| lookatme |
| looked |
| lookin |
| looking |
| looks |
| lor |
| lose |
| loses |
| losing |
| loss |
| lost |
| lot |
| lotr |
| lots |
| lotta |
| lou |
| loud |
| lounge |
| lousy |
| lov |
| lovable |
| love |
| loved |
| lovely |
| loveme |
| lover |
| loverboy |
| lovers |
| loves |
| loving |
| low |
| lower |
| loxahatchee |
| loyal |
| loyalty |
| ls1 |
| lst |
| lt |
| ltd |
| lttrs |
| luck |
| lucky |
| lucozade |
| lucy |
| lunch |
| lush |
| luv |
| luvs |
| lux |
| luxury |
| lv |
| lvblefrnd |
| lyf |
| lyfu |
| lyk |
| m221bp |
| m26 |
| m263uz |
| m6 |
| m8s |
| m95 |
| ma |
| mac |
| machan |
| macho |
| mad |
| madam |
| made |
| maga |
| magical |
| mah |
| mahal |
| maid |
| mailbox |
| mails |
| main |
| maintain |
| major |
| make |
| makes |
| makin |
| making |
| malaria |
| male |
| mall |
| man |
| manage |
| managed |
| management |
| manda |
| mandan |
| maneesha |
| many |
| map |
| march |
| margaret |
| mark |
| market |
| marriage |
| married |
| marry |
| mas |
| massive |
| masters |
| match |
| matches |
| mate |
| mates |
| math |
| mathematics |
| matrix3 |
| matter |
| matured |
| maturity |
| max10mins |
| maximize |
| maxå |
| may |
| mayb |
| maybe |
| mb |
| mcat |
| me |
| meal |
| mean |
| meaning |
| means |
| meant |
| meanwhile |
| measure |
| med |
| medical |
| medicine |
| meds |
| meet |
| meetin |
| meeting |
| meets |
| mega |
| meh |
| mei |
| mel |
| melle |
| melt |
| member |
| members |
| membership |
| men |
| mental |
| menu |
| meow |
| merry |
| mesages |
| mess |
| message |
| messages |
| messaging |
| messenger |
| messy |
| met |
| mid |
| middle |
| midnight |
| mids |
| might |
| mila |
| miles |
| milk |
| min |
| mind |
| mine |
| mini |
| minimum |
| minmobsmorelkpobox177hp51fl |
| minnaminunginte |
| mins |
| minute |
| minutes |
| minuts |
| miracle |
| mis |
| misbehaved |
| miserable |
| miss |
| missed |
| missin |
| missing |
| mistake |
| mistakes |
| mite |
| mitsake |
| mix |
| mm |
| mmm |
| mmmm |
| mmmmmm |
| mnth |
| mnths |
| mo |
| moan |
| mob |
| mobile |
| mobiles |
| mobilesdirect |
| mobilesvary |
| mobileupd8 |
| mobno |
| moby |
| mode |
| model |
| module |
| modules |
| moji |
| mokka |
| mom |
| moment |
| moments |
| moms |
| mon |
| monday |
| money |
| monkeys |
| mono |
| month |
| monthly |
| months |
| mood |
| moon |
| moral |
| more |
| morefrmmob |
| morn |
| morning |
| morphine |
| most |
| mostly |
| mother |
| motorola |
| mouth |
| move |
| moved |
| movie |
| movies |
| movietrivia |
| moving |
| mp3 |
| mr |
| mrng |
| mrt |
| ms |
| msg |
| msg150p |
| msging |
| msgrcvdhg |
| msgs |
| mt |
| mtalk |
| mth |
| mths |
| mtmsg18 |
| mtmsgrcvd18 |
| mu |
| much |
| mum |
| mummy |
| mumtaz |
| munsters |
| murder |
| murdered |
| murderer |
| music |
| must |
| musthu |
| muz |
| my |
| myself |
| n9dx |
| na |
| nag |
| nagar |
| nah |
| naked |
| nalla |
| name |
| name1 |
| name2 |
| named |
| names |
| nan |
| nap |
| nasdaq |
| nasty |
| nat |
| nat27081980 |
| natalja |
| national |
| natural |
| nature |
| naughty |
| nd |
| ne |
| near |
| nearly |
| necessary |
| neck |
| ned |
| need |
| needed |
| needs |
| neighbour |
| neither |
| net |
| netcollex |
| network |
| networking |
| networks |
| neva |
| never |
| new |
| newest |
| news |
| next |
| ni8 |
| nic |
| nice |
| nichols |
| nigeria |
| night |
| nights |
| nimya |
| nit |
| nite |
| nitros |
| no |
| no1 |
| nobody |
| noe |
| nok |
| nokia |
| nokia6600 |
| nokias |
| noline |
| none |
| noon |
| nope |
| norm |
| norm150p |
| normal |
| normally |
| northampton |
| nos |
| not |
| note |
| nothing |
| notice |
| notxt |
| now |
| nowadays |
| nt |
| ntt |
| ntwk |
| num |
| number |
| numbers |
| nurungu |
| nus |
| nvm |
| nw |
| nxt |
| ny |
| nyc |
| nydc |
| nyt |
| o2 |
| o2fwd |
| obviously |
| occupy |
| odi |
| of |
| off |
| offer |
| offers |
| office |
| official |
| ofice |
| often |
| ofå |
| oh |
| oi |
| oic |
| oil |
| ok |
| okay |
| okey |
| okie |
| ola |
| old |
| omg |
| omw |
| on |
| once |
| one |
| ones |
| oni |
| onion |
| online |
| only |
| onto |
| onwards |
| oooh |
| oops |
| open |
| operator |
| opinion |
| opinions |
| opportunity |
| opt |
| option |
| optout |
| or |
| or2stoptxt |
| orange |
| oranges |
| orchard |
| order |
| ordered |
| oredi |
| oreo |
| original |
| oru |
| os |
| oso |
| other |
| others |
| otherwise |
| otside |
| our |
| out |
| outside |
| outstanding |
| outta |
| over |
| ovulation |
| ow |
| own |
| owns |
| oz |
| pa |
| pack |
| package |
| packs |
| page |
| pages |
| paid |
| pain |
| painful |
| painting |
| pale |
| pan |
| pandy |
| panic |
| pap |
| paper |
| papers |
| paragon |
| parents |
| paris |
| park |
| parked |
| parking |
| part |
| partner |
| partnership |
| party |
| pass |
| passed |
| passionate |
| password |
| passwords |
| past |
| pattern |
| patty |
| pay |
| payee |
| paying |
| payment |
| payoh |
| pc |
| peace |
| peaceful |
| peak |
| pee |
| pence |
| pending |
| penis |
| people |
| per |
| perfect |
| perhaps |
| period |
| person |
| personal |
| personality |
| persons |
| pete |
| petey |
| petrol |
| pg |
| ph |
| philosophy |
| phne |
| phoenix |
| phone |
| phoned |
| phones |
| photo |
| photos |
| php |
| pic |
| pick |
| picked |
| picking |
| pickle |
| pics |
| picsfree1 |
| picture |
| pictures |
| pie |
| pig |
| pilates |
| pimples |
| pin |
| pink |
| piss |
| pissed |
| pix |
| pizza |
| place |
| placement |
| places |
| plan |
| plane |
| planet |
| planned |
| planning |
| plans |
| play |
| played |
| player |
| players |
| playing |
| please |
| pleased |
| pleasure |
| plenty |
| plm |
| pls |
| plus |
| plz |
| pm |
| po |
| pobox |
| pobox334 |
| pobox36504w45wq |
| pobox45w2tg150p |
| pobox84 |
| pocketbabe |
| pod |
| poem |
| point |
| points |
| poker |
| police |
| politicians |
| polo |
| poly |
| polyh |
| polyph |
| polyphonic |
| polys |
| pongal |
| pool |
| poop |
| poor |
| pop |
| popcorn |
| popped |
| porn |
| possession |
| possible |
| post |
| postcard |
| postcode |
| posted |
| posts |
| potato |
| potential |
| potter |
| pouch |
| pound |
| pounds |
| pours |
| pouts |
| power |
| ppl |
| pple |
| ppm |
| prabha |
| practical |
| practice |
| practicing |
| pray |
| praying |
| pre |
| prefer |
| preferably |
| prem |
| premium |
| prepaid |
| prepare |
| prepared |
| prepayment |
| present |
| press |
| pressies |
| pressure |
| prestige |
| pretend |
| pretsorginta |
| pretsovru |
| pretty |
| prevent |
| previews |
| previous |
| previously |
| prey |
| price |
| prices |
| pride |
| priest |
| prin |
| prince |
| princes |
| princess |
| printed |
| printer |
| printing |
| prior |
| priscilla |
| privacy |
| private |
| prix |
| priya |
| prize |
| prizeawaiting |
| prizes |
| prob |
| probably |
| problem |
| problematic |
| problems |
| problum |
| probs |
| probthat |
| process |
| processed |
| prods |
| products |
| prof |
| professors |
| profile |
| profit |
| program |
| programs |
| progress |
| project |
| projects |
| prolly |
| prometazine |
| prominent |
| promise |
| promised |
| promises |
| promo |
| promoting |
| promotion |
| promptly |
| prompts |
| prone |
| proof |
| proove |
| proper |
| properly |
| property |
| propose |
| props |
| propsd |
| pros |
| prospects |
| protect |
| proverb |
| provided |
| provider |
| providing |
| province |
| proze |
| ps |
| ps3 |
| pshew |
| psp |
| psychiatrist |
| psychic |
| psychologist |
| pt2 |
| ptbo |
| pthis |
| pub |
| public |
| publish |
| pubs |
| pudunga |
| pull |
| pulling |
| pulls |
| pump |
| punch |
| punish |
| punj |
| puppy |
| pura |
| purchase |
| purchases |
| pure |
| purity |
| purple |
| purpose |
| purse |
| push |
| pushbutton |
| pushes |
| pussy |
| put |
| puts |
| puttin |
| putting |
| puzzeles |
| puzzles |
| px3748 |
| på |
| qatar |
| qbank |
| qet |
| qi |
| qing |
| qlynnbv |
| quality |
| quarter |
| que |
| queen |
| queries |
| ques |
| question |
| questioned |
| questions |
| quick |
| quickly |
| quiet |
| quit |
| quite |
| quiteamuzing |
| quitting |
| quiz |
| quizclub |
| quizzes |
| quote |
| quoting |
| r836 |
| racal |
| racing |
| radiator |
| radio |
| raed |
| rael |
| raglan |
| rahul |
| raiden |
| railway |
| rain |
| raining |
| raise |
| raised |
| raj |
| rajas |
| raji |
| rajini |
| rajitha |
| rajnikant |
| rakhesh |
| raksha |
| rally |
| ralphs |
| ramaduth |
| ran |
| random |
| randomlly |
| randomly |
| randy |
| rang |
| ranjith |
| ranju |
| raping |
| rate |
| rates |
| rather |
| ratio |
| rats |
| raviyog |
| rawring |
| rayan |
| rayman |
| rays |
| rcb |
| rcd |
| rct |
| rcv |
| rcvd |
| rd |
| rdy |
| re |
| reach |
| reache |
| reached |
| reaching |
| reacting |
| reaction |
| read |
| readers |
| readiness |
| reading |
| ready |
| real |
| real1 |
| realise |
| realised |
| realising |
| reality |
| realize |
| realized |
| realizes |
| really |
| realy |
| reapply |
| rearrange |
| reason |
| reasonable |
| reasons |
| reassurance |
| reassuring |
| rebel |
| reboot |
| rebooting |
| rebtel |
| rec |
| recd |
| receipt |
| receipts |
| receive |
| receivea |
| received |
| receiving |
| recent |
| recently |
| reception |
| recession |
| recharge |
| recharged |
| recieve |
| reckon |
| recognise |
| recognises |
| record |
| recorded |
| recorder |
| records |
| recount |
| recovery |
| recpt |
| recreation |
| recycling |
| red |
| redeemed |
| reduce |
| ree |
| ref |
| reference |
| references |
| referin |
| refilled |
| reflection |
| reflex |
| reformat |
| refreshed |
| refunded |
| refused |
| reg |
| regard |
| regarding |
| regards |
| register |
| registered |
| regret |
| regretted |
| regular |
| rejected |
| related |
| relation |
| relatives |
| relax |
| relaxing |
| released |
| reliant |
| relieved |
| religiously |
| relocate |
| reltnship |
| rem |
| remain |
| remains |
| remb |
| remember |
| remembered |
| rememberi |
| remembr |
| remembrs |
| remind |
| reminded |
| reminder |
| reminding |
| reminds |
| remixed |
| removal |
| remove |
| removed |
| rencontre |
| renewal |
| renewed |
| renewing |
| rent |
| rental |
| renting |
| rentl |
| rents |
| repair |
| repairs |
| repeat |
| repeating |
| repent |
| replace |
| replacement |
| replacing |
| replied |
| replies |
| reply |
| replying |
| replys150 |
| report |
| reppurcussions |
| representative |
| republic |
| request |
| requests |
| require |
| required |
| requirements |
| requires |
| research |
| resend |
| resent |
| reservations |
| reserve |
| reserved |
| reserves |
| reset |
| resizing |
| reslove |
| resolution |
| resolved |
| resort |
| respect |
| respectful |
| responce |
| respond |
| responding |
| response |
| responsibilities |
| responsibility |
| responsible |
| rest |
| restaurant |
| restock |
| restocked |
| restrict |
| restrictions |
| resubbing |
| resubmit |
| result |
| results |
| resume |
| resuming |
| retard |
| retired |
| retrieve |
| return |
| returned |
| returning |
| returns |
| reunion |
| reveal |
| revealed |
| revealing |
| reverse |
| review |
| revision |
| reward |
| rewarding |
| rg21 |
| rgds |
| rgent |
| rhode |
| rhythm |
| rice |
| rich |
| riddance |
| ridden |
| ride |
| right |
| rightio |
| rightly |
| rights |
| riley |
| rimac |
| ring |
| ringing |
| rings |
| ringtone |
| ringtones |
| ringtoneåá |
| rinu |
| rip |
| ripped |
| risk |
| risks |
| rite |
| ritten |
| river |
| road |
| roads |
| roast |
| rob |
| robinson |
| robs |
| rock |
| rocks |
| rodds1 |
| rodger |
| rofl |
| roger |
| role |
| roles |
| rolled |
| roller |
| romantic |
| romcapspam |
| ron |
| room |
| roomate |
| roommate |
| roommates |
| rooms |
| ros |
| rose |
| roses |
| rough |
| round |
| rounder |
| rounds |
| route |
| row |
| rowdy |
| rows |
| royal |
| rpl |
| rply |
| rr |
| rs |
| rstm |
| rtf |
| rtm |
| rto |
| ru |
| rub |
| rubber |
| rude |
| rudi |
| rugby |
| ruin |
| ruining |
| rule |
| rules |
| rum |
| rumbling |
| rummer |
| rumour |
| run |
| running |
| runs |
| rupaul |
| rush |
| rushing |
| rv |
| rvx |
| rwm |
| ryan |
| s3xy |
| s89 |
| sabarish |
| sac |
| sachin |
| sack |
| sacked |
| sacrifice |
| sad |
| sae |
| saeed |
| safe |
| safely |
| safety |
| sagamu |
| said |
| sake |
| salad |
| salam |
| salary |
| sale |
| sales |
| salesman |
| salmon |
| salon |
| salt |
| sam |
| samachara |
| samantha |
| sambar |
| same |
| samus |
| sandiago |
| sane |
| sang |
| sankatmochan |
| sankranti |
| santa |
| santacalling |
| sao |
| sapna |
| sar |
| sara |
| sarcasm |
| sarcastic |
| saristar |
| sariyag |
| sary |
| sashimi |
| sat |
| satanic |
| sathy |
| sathya |
| satisfied |
| satisfy |
| satsgettin |
| saturday |
| saucy |
| savamob |
| save |
| saved |
| savings |
| saw |
| say |
| sayin |
| saying |
| says |
| sayy |
| sc |
| scallies |
| scammers |
| scarcasim |
| scared |
| scary |
| scenario |
| scenery |
| sch |
| schedule |
| school |
| schools |
| science |
| scold |
| scorable |
| score |
| scores |
| scoring |
| scotch |
| scotland |
| scotsman |
| scouse |
| scraped |
| scrappy |
| scratches |
| scratching |
| scream |
| screamed |
| screaming |
| screen |
| screwd |
| scrounge |
| scrumptious |
| sculpture |
| sd |
| sday |
| se |
| sea |
| search |
| searching |
| season |
| seat |
| sec |
| second |
| seconds |
| secret |
| secretary |
| secretly |
| secrets |
| secs |
| section |
| sections |
| secure |
| secured |
| sed |
| see |
| seeds |
| seeing |
| seekers |
| seeking |
| seem |
| seemed |
| seems |
| seen |
| sef |
| seh |
| sehwag |
| seing |
| select |
| selected |
| selection |
| self |
| selfindependence |
| selfish |
| selflessness |
| sell |
| selling |
| sells |
| sem |
| semester |
| semi |
| semiobscure |
| sen |
| send |
| sender |
| sending |
| sends |
| senor |
| senrd |
| sense |
| senses |
| sensible |
| sensitive |
| sent |
| sentence |
| senthil |
| sentiment |
| seperated |
| sept |
| serena |
| series |
| serious |
| seriously |
| served |
| service |
| services |
| serving |
| servs |
| set |
| setting |
| settings |
| settle |
| settled |
| settling |
| seven |
| seventeen |
| several |
| sex |
| sexiest |
| sextextuk |
| sexual |
| sexy |
| sexychat |
| sez |
| sg |
| sh |
| sha |
| shade |
| shag |
| shagged |
| shah |
| shahjahan |
| shakara |
| shake |
| shakespeare |
| shall |
| shame |
| shampain |
| shangela |
| shanghai |
| shanil |
| shant |
| shaping |
| share |
| shared |
| sharing |
| shattered |
| shaved |
| shb |
| shd |
| she |
| sheets |
| sheffield |
| shelf |
| shell |
| shelves |
| sherawat |
| shes |
| shesil |
| shhhhh |
| shifad |
| shijas |
| shijutta |
| shinco |
| shindig |
| shining |
| shiny |
| ship |
| shipped |
| shipping |
| shirt |
| shirts |
| shit |
| shite |
| shitin |
| shitinnit |
| shitload |
| shivratri |
| shld |
| shldxxxx |
| shock |
| shocking |
| shoes |
| shola |
| shoot |
| shop |
| shoppin |
| shopping |
| shoranur |
| shore |
| short |
| shortage |
| shortbreaks |
| shortcode |
| shorter |
| shortly |
| shorts |
| shot |
| shoul |
| should |
| shoulders |
| shouldn |
| shouted |
| shouting |
| shove |
| shoving |
| show |
| showed |
| shower |
| showered |
| showers |
| showing |
| showr |
| showrooms |
| shows |
| shracomorsglsuplt |
| shrink |
| shrub |
| shsex |
| shu |
| shud |
| shuhui |
| shut |
| shy |
| si |
| sian |
| sib |
| sic |
| sick |
| sickness |
| side |
| sigh |
| sighs |
| sight |
| sign |
| signal |
| significant |
| signing |
| silent |
| silently |
| silver |
| sim |
| simple |
| simpler |
| simply |
| since |
| sinco |
| sing |
| singing |
| single |
| singles |
| sipix |
| sir |
| sis |
| sister |
| sit |
| site |
| sitll |
| sitting |
| situation |
| six |
| size |
| sk3 |
| sk38xh |
| skilgme |
| skip |
| sky |
| skype |
| slap |
| slave |
| sleep |
| sleepin |
| sleeping |
| sleepwell |
| sleepy |
| slept |
| slice |
| slide |
| slightly |
| slip |
| slippers |
| slo |
| slots |
| slow |
| slowly |
| small |
| smart |
| smashed |
| smeone |
| smile |
| smiles |
| smiling |
| smith |
| smoke |
| smokes |
| smoking |
| sms |
| smth |
| sn |
| snake |
| snogs |
| snow |
| snowman |
| so |
| social |
| sofa |
| soft |
| soiree |
| sol |
| solve |
| solved |
| some |
| some1 |
| somebody |
| someone |
| somethin |
| something |
| sometime |
| sometimes |
| somewhere |
| song |
| songs |
| sony |
| sonyericsson |
| soo |
| soon |
| sooner |
| sore |
| sorrow |
| sorry |
| sort |
| sorted |
| sorting |
| sory |
| soryda |
| soul |
| sound |
| sounds |
| soup |
| source |
| south |
| sp |
| space |
| spanish |
| speak |
| speaking |
| special |
| specially |
| specific |
| speechless |
| speed |
| speedchat |
| speeding |
| spell |
| spend |
| spending |
| spent |
| spider |
| spile |
| spk |
| spl |
| splleing |
| spoiled |
| spoke |
| spoken |
| spook |
| sport |
| sports |
| spree |
| sptv |
| sry |
| st |
| staff |
| stamped |
| stamps |
| stand |
| standard |
| standing |
| star |
| staring |
| stars |
| start |
| started |
| starting |
| starts |
| starwars3 |
| statement |
| station |
| status |
| stay |
| stayed |
| stayin |
| staying |
| stays |
| std |
| steam |
| step |
| steve |
| stick |
| sticky |
| still |
| stock |
| stockport |
| stomach |
| stomps |
| stones |
| stop |
| stopped |
| stops |
| store |
| stores |
| storming |
| story |
| str |
| straight |
| strange |
| stranger |
| street |
| stress |
| strike |
| strong |
| stuck |
| student |
| students |
| study |
| studying |
| stuff |
| stupid |
| style |
| stylish |
| sub |
| subpoly |
| subs |
| subs16 |
| subscribe6gbp |
| subscribed |
| subscriber |
| subscription |
| successful |
| successfully |
| sucks |
| sufficient |
| sugar |
| suggest |
| suite |
| suite342 |
| sum |
| sum1 |
| summer |
| summers |
| sumthin |
| sun |
| sunday |
| sunlight |
| sunny |
| sunshine |
| sup |
| super |
| superb |
| superior |
| supervisor |
| supply |
| support |
| suppose |
| supposed |
| suprman |
| sura |
| sure |
| surely |
| surfing |
| surprise |
| surprised |
| suzy |
| sw7 |
| sw73ss |
| swatch |
| sweet |
| sweetest |
| sweetheart |
| sweetie |
| sweets |
| swimming |
| swing |
| swiss |
| switch |
| swt |
| swtheart |
| symbol |
| system |
| ta |
| table |
| tablets |
| tacos |
| tahan |
| take |
| taken |
| takes |
| takin |
| taking |
| talent |
| talk |
| talking |
| talks |
| tampa |
| tank |
| tap |
| tape |
| tariffs |
| tat |
| taunton |
| taxi |
| taylor |
| tayseer |
| tb |
| tc |
| tcr |
| tcs |
| tea |
| teach |
| teacher |
| teaches |
| teaching |
| team |
| tear |
| tease |
| teasing |
| tech |
| technical |
| tee |
| teeth |
| tel |
| telephone |
| tell |
| telling |
| tells |
| telly |
| telphone |
| telugu |
| temp |
| temple |
| ten |
| tenants |
| tenerife |
| tension |
| term |
| terms |
| terrible |
| terrific |
| terrorist |
| tessy |
| test |
| testing |
| tests |
| text |
| textbuddy |
| textcomp |
| texted |
| texting |
| textoperator |
| textpod |
| texts |
| th |
| than |
| thangam |
| thank |
| thanks |
| thanksgiving |
| thanx |
| that |
| thats |
| thatåõs |
| the |
| theatre |
| their |
| them |
| themob |
| then |
| theory |
| there |
| theres |
| these |
| they |
| thing |
| things |
| think |
| thinkin |
| thinking |
| thinks |
| this |
| thk |
| thm |
| thnk |
| tho |
| those |
| thot |
| though |
| thought |
| thoughts |
| thousands |
| thread |
| threats |
| three |
| threw |
| throat |
| through |
| throw |
| thru |
| ths |
| tht |
| thts |
| thurs |
| thursday |
| thx |
| thy |
| tick |
| ticket |
| tickets |
| tight |
| tihs |
| til |
| till |
| time |
| times |
| timing |
| tired |
| tirunelvali |
| tirupur |
| tis |
| tissco |
| title |
| titles |
| tiwary |
| tkts |
| tlk |
| tlp |
| tm |
| tmr |
| tms |
| tnc |
| tncs |
| to |
| toa |
| toclaim |
| today |
| todays |
| tog |
| together |
| tok |
| told |
| toll |
| tom |
| tomarrow |
| tomo |
| tomorrow |
| tone |
| tones |
| tones2u |
| tonight |
| tonights |
| tonite |
| tons |
| too |
| took |
| tool |
| tooo |
| toot |
| tooth |
| top |
| topic |
| torch |
| tortilla |
| tosend |
| toshiba |
| toss |
| tot |
| total |
| totally |
| totes |
| touch |
| touched |
| tough |
| toughest |
| tour |
| towards |
| town |
| toxic |
| tp |
| track |
| trackmarque |
| trade |
| traditions |
| traffic |
| train |
| trained |
| training |
| trainners |
| trains |
| tram |
| tranquility |
| transaction |
| transcribing |
| transfer |
| transfered |
| transferred |
| transfr |
| transfred |
| transport |
| trash |
| trauma |
| trav |
| travel |
| traveling |
| travelled |
| travelling |
| treacle |
| treadmill |
| treasure |
| treat |
| treated |
| treatin |
| treats |
| trebles |
| tree |
| trends |
| trial |
| tried |
| trip |
| triple |
| trips |
| trishul |
| triumphed |
| trivia |
| tron |
| trouble |
| troubleshooting |
| trouser |
| truble |
| truck |
| true |
| true18 |
| trueåác |
| truffles |
| truly |
| trust |
| trusting |
| truth |
| try |
| tryin |
| trying |
| ts |
| tsandcs |
| tscs |
| tscs08714740323 |
| tscs087147403231winawk |
| tsunami |
| tsunamis |
| tt |
| ttyl |
| tue |
| tues |
| tuesday |
| tui |
| tuition |
| tul |
| tulip |
| tunde |
| tune |
| turkeys |
| turn |
| turned |
| turning |
| turns |
| tuth |
| tv |
| twat |
| twelve |
| twenty |
| twice |
| twiggs |
| twilight |
| twinks |
| twins |
| twittering |
| two |
| txt |
| txt250 |
| txt43 |
| txt82228 |
| txtauction |
| txtin |
| txting |
| txtno |
| txts |
| txtstar |
| txtstop |
| txttowin |
| txtx |
| tyler |
| type |
| types |
| typical |
| tyrone |
| u4 |
| uawake |
| ubandu |
| ubi |
| ud |
| ugadi |
| ugh |
| ugo |
| uh |
| uhhhhrmm |
| uin |
| ujhhhhhhh |
| uk |
| ukp |
| uks |
| ultimate |
| ultimately |
| ultimatum |
| um |
| umma |
| ummifying |
| ummma |
| ummmmmaah |
| un |
| unable |
| unbelievable |
| unbreakable |
| unclaimed |
| uncle |
| uncles |
| uncomfortable |
| unconditionally |
| unconscious |
| unconsciously |
| unconvinced |
| uncut |
| under |
| underdtand |
| understand |
| understanding |
| understood |
| underwear |
| undrstnd |
| undrstndng |
| unemployed |
| unfolds |
| unfortunately |
| unfortuntly |
| unhappiness |
| unhappy |
| uni |
| unicef |
| uniform |
| unintentionally |
| unique |
| united |
| units |
| univ |
| university |
| unjalur |
| unkempt |
| unknown |
| unless |
| unlike |
| unlimited |
| unmits |
| unnecessarily |
| unni |
| unrecognized |
| unredeemed |
| unsecured |
| unsold |
| unsub |
| unsubscribe |
| unsubscribed |
| untamed |
| until |
| unusual |
| up |
| up4 |
| upcharge |
| upd8 |
| updat |
| update |
| update_now |
| upgrade |
| upgrading |
| upgrdcentre |
| upload |
| uploaded |
| upon |
| upping |
| ups |
| upset |
| upstairs |
| upto |
| uptown |
| ur |
| urawinner |
| ure |
| urfeeling |
| urgent |
| urgently |
| urgnt |
| urgoin |
| urination |
| url |
| urmom |
| urn |
| urself |
| us |
| usa |
| usb |
| usc |
| use |
| used |
| useful |
| useless |
| user |
| uses |
| usf |
| usher |
| using |
| usmle |
| usps |
| usual |
| usually |
| uterus |
| utter |
| uttered |
| uup |
| uve |
| uworld |
| va |
| vaazhthukkal |
| vague |
| vale |
| valentine |
| valentines |
| valid |
| valid12hrs |
| valuable |
| value |
| valued |
| values |
| valuing |
| varaya |
| vargu |
| various |
| varma |
| varunnathu |
| vary |
| vasai |
| vat |
| vatian |
| vava |
| vco |
| vday |
| ve |
| vegas |
| vegetables |
| vehicle |
| velachery |
| venaam |
| venugopal |
| verified |
| verify |
| verifying |
| version |
| versus |
| very |
| vettam |
| vewy |
| via |
| vibrant |
| vibrate |
| vibrator |
| vic |
| victoria |
| victors |
| vid |
| video |
| videochat |
| videophones |
| videos |
| videosound |
| videosounds |
| view |
| vijay |
| vijaykanth |
| vikky |
| vilikkam |
| vill |
| villa |
| village |
| vinobanagar |
| violated |
| violence |
| violet |
| vip |
| vipclub4u |
| virgil |
| virgin |
| virgins |
| virtual |
| visa |
| visionsms |
| visit |
| visiting |
| visitor |
| visitors |
| vital |
| vitamin |
| viva |
| vl |
| voda |
| vodafone |
| vodka |
| voice |
| voicemail |
| voila |
| vomit |
| vomitin |
| vomiting |
| vote |
| voted |
| vouch4me |
| voucher |
| vouchers |
| vpod |
| vry |
| vs |
| vth |
| vu |
| w1 |
| w111wx |
| w14rg |
| w1a |
| w1j |
| w1j6hl |
| w1jhl |
| w1t1jy |
| w45wq |
| w8in |
| wa |
| waaaat |
| wad |
| wadebridge |
| wah |
| wahala |
| wahay |
| waheed |
| waheeda |
| wahleykkum |
| waht |
| wait |
| waited |
| waitin |
| waiting |
| wake |
| waking |
| wales |
| waliking |
| walk |
| walkabout |
| walked |
| walkin |
| walking |
| walks |
| wall |
| wallpaper |
| walls |
| walmart |
| walsall |
| wamma |
| wan |
| wan2 |
| wana |
| wanna |
| wannatell |
| want |
| want2come |
| wanted |
| wanting |
| wants |
| wap |
| warm |
| warner |
| warning |
| warranty |
| was |
| wasn |
| waste |
| wat |
| watch |
| watching |
| water |
| wating |
| wats |
| wave |
| waves |
| way |
| wc1n3xx |
| we |
| weak |
| wear |
| wearing |
| weather |
| web |
| webadres |
| webeburnin |
| webpage |
| website |
| wed |
| weddin |
| wedding |
| weddingfriend |
| wednesday |
| weds |
| wee |
| weed |
| week |
| weekdays |
| weekend |
| weekends |
| weekly |
| weeks |
| weigh |
| weighed |
| weight |
| weightloss |
| weird |
| weirdest |
| welcome |
| well |
| welp |
| wen |
| went |
| wer |
| were |
| werethe |
| wesley |
| west |
| wet |
| what |
| whatever |
| whats |
| when |
| whenever |
| whenevr |
| where |
| wherever |
| whether |
| which |
| while |
| white |
| whn |
| who |
| whole |
| whom |
| whos |
| whose |
| whr |
| why |
| wicklow |
| wid |
| widelive |
| wif |
| wife |
| wifi |
| wihtuot |
| wil |
| will |
| willing |
| win |
| window |
| windows |
| wine |
| winner |
| winning |
| wins |
| wipro |
| wisdom |
| wise |
| wish |
| wishes |
| wishin |
| wishing |
| wit |
| with |
| within |
| without |
| wiv |
| wk |
| wkend |
| wkent |
| wkg |
| wkly |
| wks |
| wld |
| wml |
| wn |
| wnt |
| wocay |
| woke |
| woken |
| woman |
| womdarfull |
| women |
| won |
| wondar |
| wondarfull |
| wonder |
| wonderful |
| wondering |
| wonders |
| wont |
| woo |
| woodland |
| woohoo |
| woot |
| woozles |
| worc |
| word |
| words |
| work |
| workage |
| workand |
| workin |
| working |
| workout |
| works |
| world |
| worlds |
| worried |
| worries |
| worry |
| worrying |
| worse |
| worst |
| worth |
| worthless |
| wot |
| wotu |
| wotz |
| would |
| woulda |
| wouldn |
| wounds |
| wow |
| wrc |
| wrecked |
| wrench |
| wrenching |
| wright |
| write |
| writhing |
| wrk |
| wrkin |
| wrking |
| wrks |
| wrld |
| wrnog |
| wrong |
| wrongly |
| wrote |
| ws |
| wt |
| wtc |
| wtf |
| wth |
| wthout |
| wtlp |
| wud |
| wudn |
| wuld |
| wuldnt |
| wun |
| www |
| wylie |
| x2 |
| x29 |
| x49 |
| xafter |
| xam |
| xavier |
| xchat |
| xclusive |
| xin |
| xmas |
| xoxo |
| xt |
| xuhui |
| xx |
| xxsp |
| xxuk |
| xxx |
| xxxx |
| xxxxx |
| xxxxxx |
| xxxxxxx |
| xxxxxxxx |
| xxxxxxxxxxxxxx |
| xy |
| y87 |
| ya |
| yahoo |
| yalrigu |
| yalru |
| yam |
| yan |
| yar |
| yarasu |
| yards |
| yavnt |
| yaxx |
| yay |
| yck |
| yeah |
| year |
| years |
| yeesh |
| yeh |
| yelling |
| yellow |
| yelow |
| yen |
| yeovil |
| yep |
| yer |
| yes |
| yest |
| yesterday |
| yet |
| yetty |
| yetunde |
| yhl |
| yi |
| yifeng |
| yijue |
| ym |
| ymca |
| yo |
| yoga |
| yogasana |
| yor |
| yorge |
| you |
| youdoing |
| youi |
| young |
| younger |
| youphone |
| your |
| youre |
| yourinclusive |
| yourjob |
| yours |
| yourself |
| youuuuu |
| youwanna |
| youåõre |
| yoville |
| yowifes |
| yoyyooo |
| yr |
| yrs |
| ystrday |
| ything |
| yummmm |
| yummy |
| yun |
| yunny |
| yuo |
| yuou |
| yup |
| yupz |
| zac |
| zaher |
| zealand |
| zebra |
| zed |
| zeros |
| zhong |
| zoe |
| zogtorius |
| zoom |
| zouk |
| åè10 |
| åð |
| åòharry |
| åòit |
| åômorrow |
| åôrents |
| ì_ |
| ì¼1 |
| ìä |
| ìï |
| ó_ |
| û_ |
| û_thanks |
| ûªm |
| ûªt |
| ûªve |
| ûï |
| ûïharry |
| ûò |
Parameters
Fitted attributes
Spam classification: predictions on unseen messages
These are predictions for a few unseen messages. We need a larger evaluation to judge how reliable the model is.
| sms | spam_predictions | |
|---|---|---|
| 3245 | Funny fact Nobody teaches volcanoes 2 erupt, tsunamis 2 arise, hurricanes 2 sway aroundn no 1 teaches hw 2 choose a wife Natural disasters just happens | ham |
| 944 | I sent my scores to sophas and i had to do secondary application for a few schools. I think if you are thinking of applying, do a research on cost also. Contact joke ogunrinde, her school is one me the less expensive ones | ham |
| 1044 | We know someone who you know that fancies you. Call 09058097218 to find out who. POBox 6, LS15HB 150p | spam |
| 2484 | Only if you promise your getting out as SOON as you can. And you'll text me in the morning to let me know you made it in ok. | ham |
Example: Supervised regression
Suppose we want to predict housing prices given a number of attributes associated with houses. The target here is continuous and not discrete.
| target | bedrooms | bathrooms | sqft_living | sqft_lot | floors | waterfront | view | condition | grade | sqft_above | sqft_basement | yr_built | yr_renovated | zipcode | lat | long | sqft_living15 | sqft_lot15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 509000.0 | 2 | 1.50 | 1930 | 3521 | 2.0 | 0 | 0 | 3 | 8 | 1930 | 0 | 1989 | 0 | 98007 | 47.6092 | -122.146 | 1840 | 3576 |
| 675000.0 | 5 | 2.75 | 2570 | 12906 | 2.0 | 0 | 0 | 3 | 8 | 2570 | 0 | 1987 | 0 | 98075 | 47.5814 | -122.050 | 2580 | 12927 |
| 420000.0 | 3 | 1.00 | 1150 | 5120 | 1.0 | 0 | 0 | 4 | 6 | 800 | 350 | 1946 | 0 | 98116 | 47.5588 | -122.392 | 1220 | 5120 |
| 680000.0 | 8 | 2.75 | 2530 | 4800 | 2.0 | 0 | 0 | 4 | 7 | 1390 | 1140 | 1901 | 0 | 98112 | 47.6241 | -122.305 | 1540 | 4800 |
| 357823.0 | 3 | 1.50 | 1240 | 9196 | 1.0 | 0 | 0 | 3 | 8 | 1240 | 0 | 1968 | 0 | 98072 | 47.7562 | -122.094 | 1690 | 10800 |
Predicting prices of unseen houses
| Predicted_target | bedrooms | bathrooms | sqft_living | sqft_lot | floors | waterfront | view | condition | grade | sqft_above | sqft_basement | yr_built | yr_renovated | zipcode | lat | long | sqft_living15 | sqft_lot15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 345831.740542 | 4 | 2.25 | 2130 | 8078 | 1.0 | 0 | 0 | 4 | 7 | 1380 | 750 | 1977 | 0 | 98055 | 47.4482 | -122.209 | 2300 | 8112 |
| 601042.018745 | 3 | 2.50 | 2210 | 7620 | 2.0 | 0 | 0 | 3 | 8 | 2210 | 0 | 1994 | 0 | 98052 | 47.6938 | -122.130 | 1920 | 7440 |
| 311310.186024 | 4 | 1.50 | 1800 | 9576 | 1.0 | 0 | 0 | 4 | 7 | 1800 | 0 | 1977 | 0 | 98045 | 47.4664 | -121.747 | 1370 | 9576 |
| 597555.592401 | 3 | 2.50 | 1580 | 1321 | 2.0 | 0 | 2 | 3 | 8 | 1080 | 500 | 2014 | 0 | 98107 | 47.6688 | -122.402 | 1530 | 1357 |
We are predicting continuous values here as opposed to discrete values in spam vs. ham example.
Example: Predicting image labels
- We reuse an image classifier trained elsewhere to predict labels for new photos.
- The model learned from labeled images during its original training; we do not train it here.
                                     Class  Probability score
         cheetah, chetah, Acinonyx jubatus              0.994
                  leopard, Panthera pardus              0.005
jaguar, panther, Panthera onca, Felis onca              0.001
       snow leopard, ounce, Panthera uncia              0.000
--------------------------------------------------------------
                                   Class  Probability score
                                    wing              0.084
                             toilet seat              0.081
                              car mirror              0.069
binoculars, field glasses, opera glasses              0.062
--------------------------------------------------------------
                        Class  Probability score
Walker hound, Walker foxhound              0.582
             English foxhound              0.144
                       beagle              0.068
                  EntleBucher              0.059
--------------------------------------------------------------
                      Class  Probability score
           pizza, pizza pie              0.995
frying pan, frypan, skillet              0.004
                     potpie              0.000
                 Dutch oven              0.000
--------------------------------------------------------------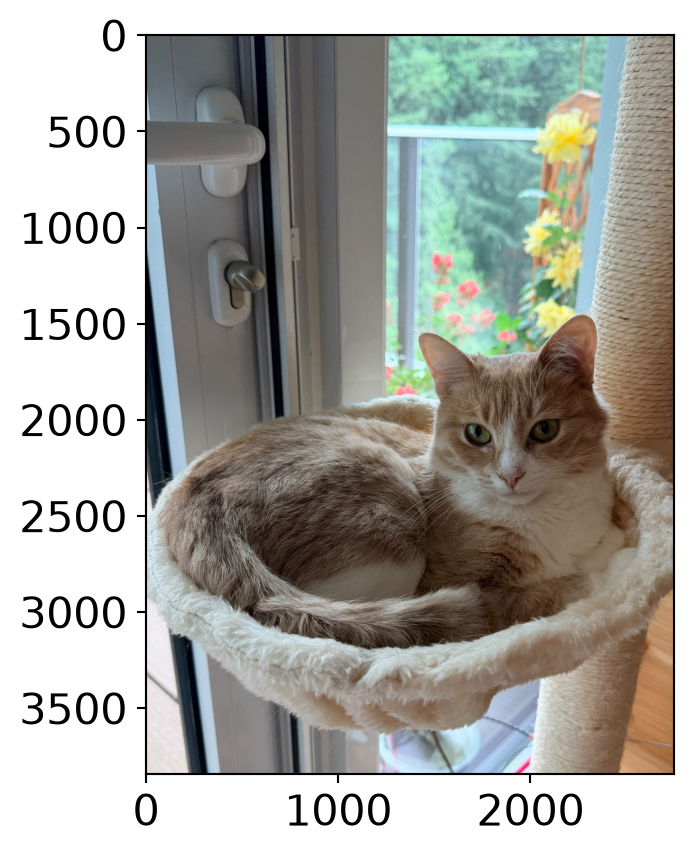
           Class  Probability score
    Egyptian cat              0.259
 lynx, catamount              0.157
       tiger cat              0.140
tabby, tabby cat              0.104
--------------------------------------------------------------
Finding groups in food images
- Clustering groups similar examples without supplied target labels.
- The image representation affects what counts as similar.
- People must interpret the groups: do they reflect food types, plate colour, or backgrounds?
Clustering images
import torch
densenet = models.densenet121(weights="DenseNet121_Weights.IMAGENET1K_V1")
densenet.classifier = torch.nn.Identity()  # remove that last "classification" layer

Z_food = get_features_unsup(densenet, food_inputs)
k = 5
km = KMeans(n_clusters=k, n_init='auto', random_state=123)
km.fit(Z_food);
Examining food clusters
199
Image indices:  [199 197 223 259 265 169]
224
Image indices:  [224  93 126 104   7 134]
6
Image indices:  [  6  72 106   1 100  26]
234
Image indices:  [234 248  41 160 180  63]
134
Image indices:  [134 257 194  93 212  86]
Learning patterns in preferences
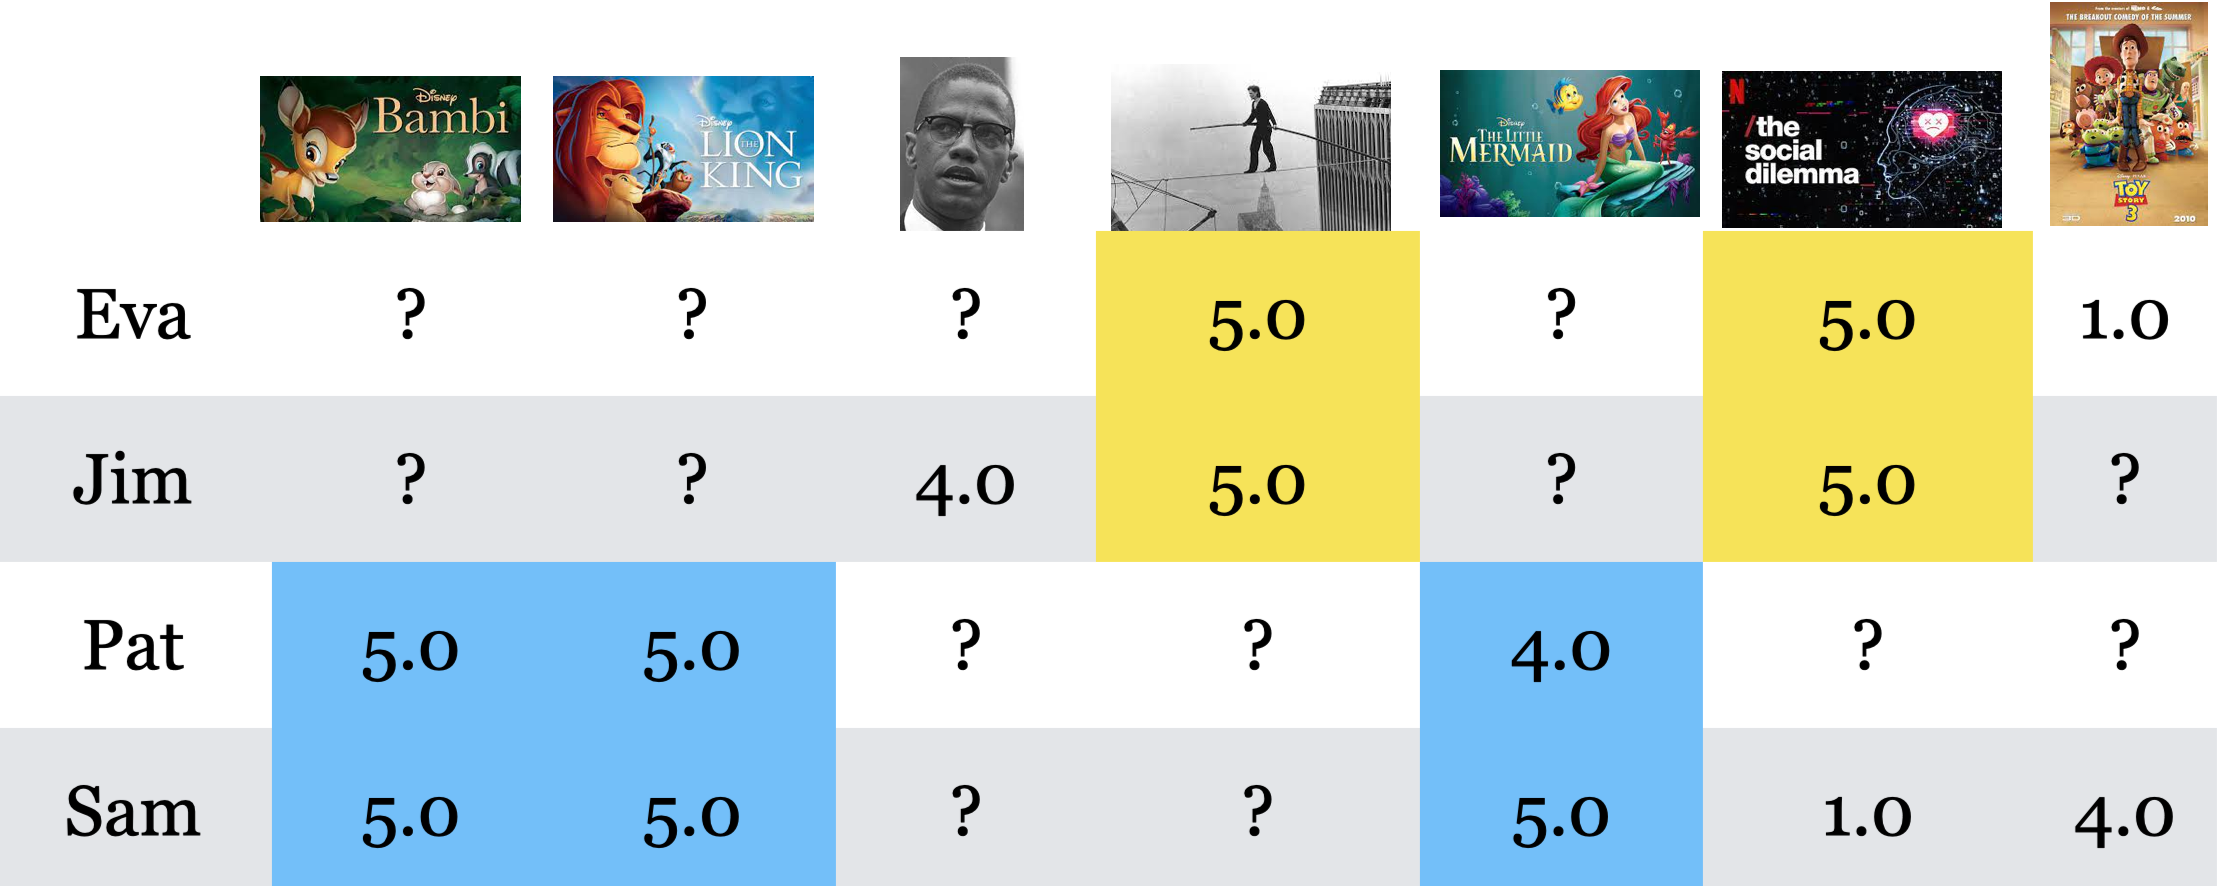
- Sam and Pat like many of the same movies. What should we recommend to Pat next?
When should we use ML?
Rules, ML, or human judgment?
| Starting point | When it is appropriate |
|---|---|
| Explicit rules | The logic is known, stable, and can be stated precisely. |
| Machine learning | Useful patterns exist in representative data, hand-written rules are difficult, and we can evaluate errors. |
| Human judgment | Context, empathy, values, or accountability are central to the decision. |
Real systems can combine all three. Making a prediction does not automatically justify delegating the decision to a model.
❓❓ Rules, ML, or human judgment?
Choose a starting point for each problem and explain why. Combinations are possible.
- (A) Checking whether an email address ends with
@student.ubc.ca - (B) Awarding a scholarship based on a student’s personal essay
- (C) Predicting which songs a listener might enjoy
- (D) Checking whether two essays are exactly identical
- (E) Tagging photos of friends
Where could mistakes cause harm, and who should be responsible?
🤔 Eva’s questions
- How can a model predict a label for an example it has never seen before?
- What happens when it makes a mistake, such as marking a genuine message as spam?
- How do we measure whether it is reliable enough to use?
These questions will guide our work throughout the course.
Developing ML solutions
In this course, we will learn to:
- Frame problems and decide what role ML should play.
- Prepare data and engineer and select useful features.
- Choose suitable methods and evaluate their results.
- Study errors, limitations, and possible harms.
- Communicate findings and explore deployment.
A trained model is one component of a solution.
Break

Course overview
Course website
Important
Use the 2026W1 course website for schedules, announcements, and policies. Read the syllabus carefully. The separate course book contains our shared notes.
Important
Make sure you go through the syllabus thoroughly and complete the syllabus quiz before Sept 19th at 11:59pm.
What do we cover
- Designed for a diverse group of students (CS, Statistics, and beyond)
- Gentle introduction to machine learning, but also valuable for those with prior experience
- Covers foundational concepts in ML and data science:
- Data preprocessing, supervised learning, clustering
- Recommendation systems, text processing
- Intro to neural networks, time series, survival analysis
- Data preprocessing, supervised learning, clustering
- Emphasis on hands-on skills:
- Model development, evaluation, interpretation
- Ethical considerations and clear communication
- Model development, evaluation, interpretation
Course structure
- Part I: Foundations and Supervised Learning
- Weeks 2, 3, 4, 5, 6, 7
- Unsupervised Learning and Recommendation
- Weeks 8, 9
- Working with Different Data Types
- Weeks 9, 11, 12
- Responsible Machine Learning in Practice
- Weeks 12, 13
CPSC 330 vs. 340
Read 330_vs_340 which explains the difference between two courses.
TLDR:
- 340: how do ML models work?
- 330: how do I use ML models and develop ML solutions?
- CPSC 340 has many prerequisites.
- CPSC 340 goes deeper but has a more narrow scope.
- I think CPSC 330 will be more useful if you just plan to apply basic ML.
Lecture format
- In person lectures T/Th.
- Sometimes there will be videos to watch before lecture. You will find the list of pre-watch videos in the schedule on the course webpage.
- We will also try to work on some questions and exercises together during the class.
- Use the course website for the schedule and slides, and the course book for shared notes.
Tutorials
- Weekly tutorials will be run by the TAs.
- Participation is worth 5% of the course grade and is planned to be assessed during tutorials starting next week. Details will be announced.
- Make use of this helpful resource.
Lecture notes and slides
- Read the shared notes in the CPSC 330 course book.
- For this lecture, read Chapter 1: Course Introduction.
- Each instructor prepares slides and demos based on the book.
- Use the 2026W1 course website for deadlines and policies.
Registration, waitlist and prerequisites
Important
Please go through this document carefully before contacting your instructors about these issues. Even then, we are very unlikely to be able to help with registration, waitlist or prerequisite issues.
- See the current syllabus for registration and waitlist deadlines.
- If you are on the waitlist and would like to try your chances, you should already have access to Ed Discussion and PrairieLearn.
- Please note that it is your responsibility to complete and submit all assessments while you are on the waitlist. No concessions will be made for students who are waitlisted.
- Instructors cannot change the waitlist order or help you bypass it.
Setting up your computer for the course
Tools used in this course
We will use the following tools throughout the course:
- Coding:
Python, with eitherJupyter LaborVS Code - Version Control:
gitandGitHub - Assignment Submission:
PrairieLearn - Discussion Forum:
Ed Discussion - Exams and Final Grades:
PrairieLearnandCanvas - Recommended Browsers: Google Chrome or Mozilla Firefox
Course Python environment
- Follow the setup instructions here to set up the course Python environment with
uvon your computer. - If you do not have your computer with you, you can partner up with someone and set up your own computer later.
Python requirements/resources
We will primarily use Python in this course.
Here is the basic Python knowledge you’ll need for the course:
- Basic Python programming
- Numpy
- Pandas
- Basic matplotlib
Homework 1 is all about Python.
Note
We do not have time to teach all the Python we need but you can find some useful Python resources here.
Workload
What does a typical week look like?
Before class: Watch pre-lecture videos or preview notes
In class: Two 80-minute lectures with iClicker questions, activities, and live demos
Support: Weekly tutorials and office hours
Practice: Weekly assignments (except exam weeks)
Tips for success:
Attend lectures regularly and ask questions
Start homework early. Hands-on practice is essential
Use Generative AI tools responsibly. No blind copy-pasting
Always question your data, methods, and results. Justify your choices.
Course policies
Attendance
Scenario: I can learn just as well from home
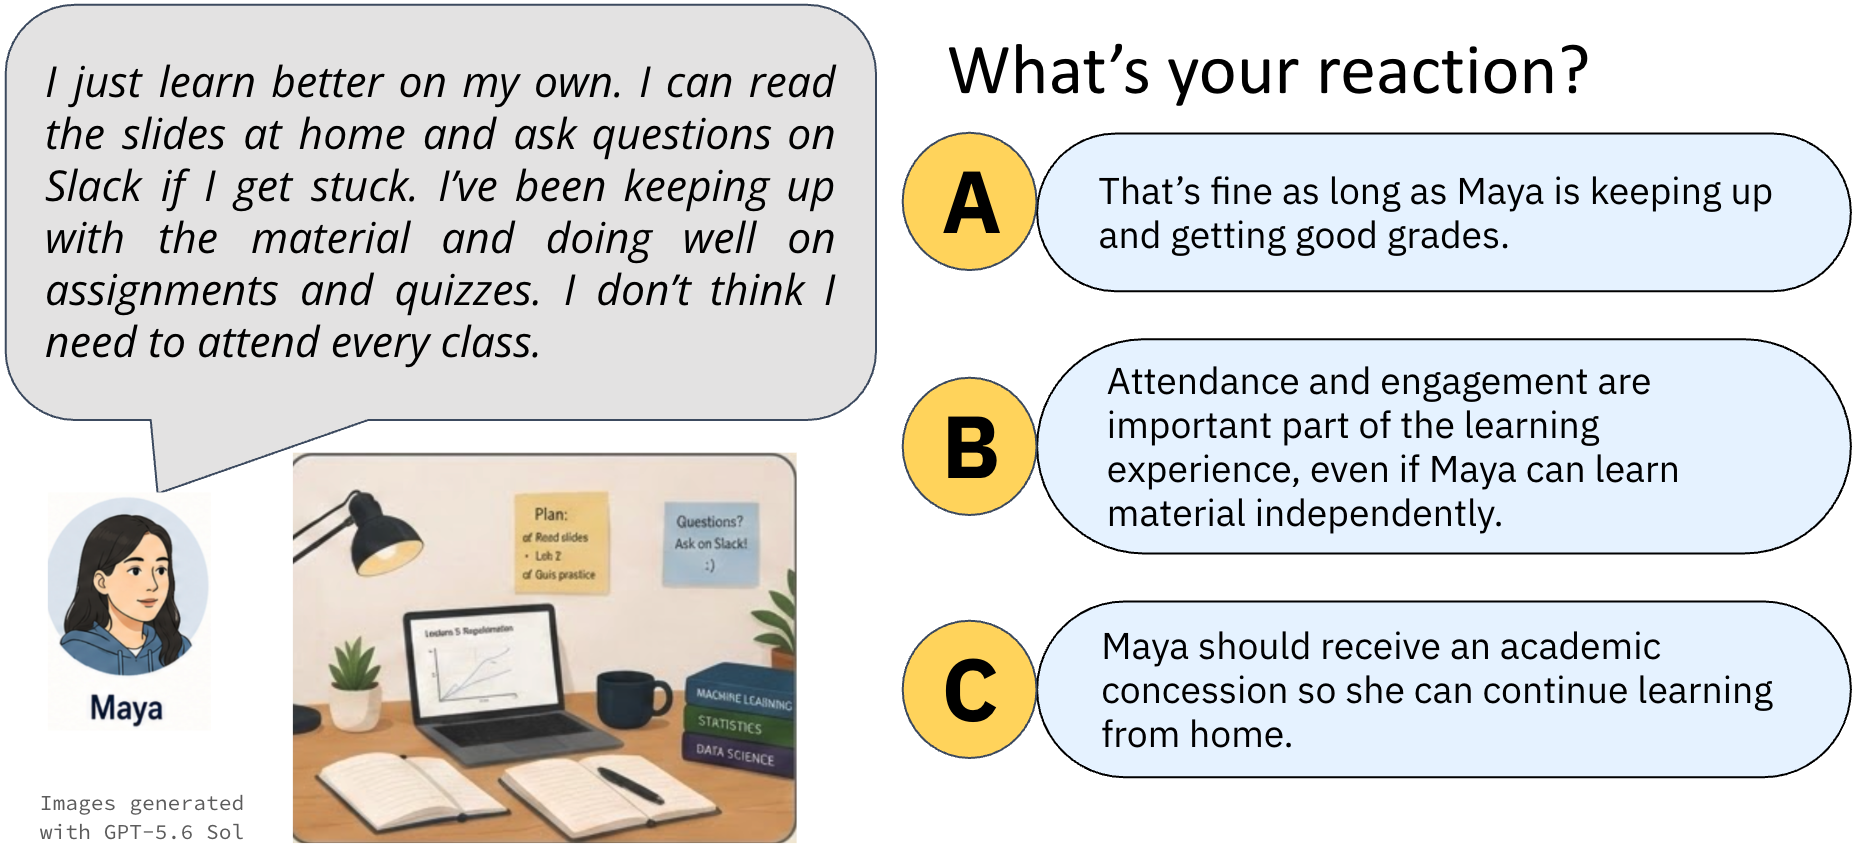
Your presence and engagement matters!! Together we create energy that makes lectures valuable!
Grading scheme
Exams
- Two midterms, conducted in ORCA by self-reservation over a multi-day period.
- A comprehensive final exam during the exam period.
- Check the course website for dates and assessment instructions.
Homework assignments
- Our notes are created in a Jupyter notebook, with file extension
.ipynb. - Also, you will complete your homework assignments using Jupyter notebooks.
- Confusingly, “Jupyter notebook” is also the original application that opens
.ipynbfiles - but has since been replaced by Jupyter Lab.- I am using Jupyter Lab, some things might not work with the Jupyter notebook application.
- You can also open these files in Visual Studio Code.
Important note
- Note that your first homework assignment is due Monday, September 14, 11:59 PM (tentative; check the course schedule). This is a relatively straightforward assignment on Python.
- If you struggle with this assignment then that could be a sign that you will struggle later on in the course.
- Write your own answers and code unless the assignment explicitly permits group work.
Plagiarism
Raise your hand if you’ve ever copied code from StackOverflow.
- Copying isn’t always wrong but not acknowledging it is.
- Plagiarism may lead to serious consequences
Using generative AI in this course
Please read our full Generative AI usage policy.
TL;DR: use AI to support, not substitute, your work. If you use a tool:
- Name the tool and briefly explain how you used it.
- Be able to explain and reproduce your work without the tool.
- Do not share instructor-provided course materials or sensitive information without permission.
- GenAI is not permitted during exams or timed assessments unless explicitly allowed.
- Follow group-work rules and be extra careful when collaborating.
- You are responsible for any errors (“hallucinations”) the tool produces.
Who to contact: Grading concerns?
- Start by opening a regrade request.
- If not resolved in two weeks, reach out to your section instructor on Ed Discussion
Who to contact: admin stuff/concessions?
- Read Frequently Asked Questions before contacting.
- Contact our course co-ordinator
Who to contact: Questions on the content?
- Make sure to read our guide on asking for help before reaching out.
- Post your question on Ed Discussion.
- Make use of instructor and TA office hours and tutorials
- I am open to answering questions after class.
Code of conduct
- Our main forum for getting help will be Ed Discussion.
Important
Please read this entire document about asking for help. TLDR: Be respectful.
Asking questions during class
- You are encouraged to ask questions by raising your hand.
- No question is a stupid question.
- Recommended reading as you begin your learning journey: The Fear of Publicly Not Knowing
What I quickly came to realize was that publicly not knowing wasn’t a indicator of stupidity, it was an indicator of understanding. And from what I’ve seen, it is one of the clearest indicators of success in people — more than school prestige, more than GPA.
Checklist for you before the next class
Optional demos and activities
These examples extend the main lecture and can be explored as time permits.
Example: Supervised classification
- We want to predict liver disease from tabular features:
| Age | Total_Bilirubin | Direct_Bilirubin | Alkaline_Phosphotase | Alamine_Aminotransferase | Aspartate_Aminotransferase | Total_Protiens | Albumin | Albumin_and_Globulin_Ratio | Target |
|---|---|---|---|---|---|---|---|---|---|
| 40 | 14.5 | 6.4 | 358 | 50 | 75 | 5.7 | 2.1 | 0.50 | Disease |
| 33 | 0.7 | 0.2 | 256 | 21 | 30 | 8.5 | 3.9 | 0.80 | Disease |
| 24 | 0.7 | 0.2 | 188 | 11 | 10 | 5.5 | 2.3 | 0.71 | No Disease |
| 60 | 0.7 | 0.2 | 171 | 31 | 26 | 7.0 | 3.5 | 1.00 | No Disease |
| 18 | 0.8 | 0.2 | 199 | 34 | 31 | 6.5 | 3.5 | 1.16 | No Disease |
Model training
LGBMClassifier(n_jobs=1, random_state=123, verbosity=-1)In a Jupyter environment, please rerun this cell to show the HTML representation or trust the notebook.
On GitHub, the HTML representation is unable to render, please try loading this page with nbviewer.org.
Parameters
| random_state | 123 | |
| n_jobs | 1 | |
| verbosity | -1 | |
| boosting_type | 'gbdt' | |
| num_leaves | 31 | |
| max_depth | -1 | |
| learning_rate | 0.1 | |
| n_estimators | 100 | |
| subsample_for_bin | 200000 | |
| objective | None | |
| class_weight | None | |
| min_split_gain | 0.0 | |
| min_child_weight | 0.001 | |
| min_child_samples | 20 | |
| subsample | 1.0 | |
| subsample_freq | 0 | |
| colsample_bytree | 1.0 | |
| reg_alpha | 0.0 | |
| reg_lambda | 0.0 | |
| importance_type | 'split' |
Fitted attributes
| Name | Type | Value |
|---|---|---|
| best_iteration_ | int | 0 |
| best_score_ | defaultdict | defaultdict(<...redDict'>, {}) |
| booster_ | Booster | <lightgbm.bas...t 0x1098c7710> |
| classes_ | ndarray[object](2,) | ['Disease','No Disease'] |
| evals_result_ | dict | {} |
| feature_importances_ | ndarray[int32](9,) | [356,178,127,...,209,240,176] |
| feature_name_ | list | ['Age', 'To...in', 'Di...in', 'Al...se', ...] |
| feature_names_in_ | ndarray[<U26](9,) | ['Age','Total_Bilirubin','Direct_Bilirubin',...,'Total_Protiens','Albumin', 'Albumin_and_Globulin_Ratio'] |
| fitted_ | bool | True |
| n_classes_ | int | 2 |
| n_estimators_ | int | 100 |
| n_features_ | int | 9 |
| n_features_in_ | int | 9 |
| n_iter_ | int | 100 |
| objective_ | str | 'binary' |
New examples
- Given features of new patients below we’ll use this model to predict whether these patients have the liver disease or not.
| Age | Total_Bilirubin | Direct_Bilirubin | Alkaline_Phosphotase | Alamine_Aminotransferase | Aspartate_Aminotransferase | Total_Protiens | Albumin | Albumin_and_Globulin_Ratio |
|---|---|---|---|---|---|---|---|---|
| 19 | 1.4 | 0.8 | 178 | 13 | 26 | 8.0 | 4.6 | 1.30 |
| 12 | 1.0 | 0.2 | 719 | 157 | 108 | 7.2 | 3.7 | 1.00 |
| 60 | 5.7 | 2.8 | 214 | 412 | 850 | 7.3 | 3.2 | 0.78 |
| 42 | 0.5 | 0.1 | 162 | 155 | 108 | 8.1 | 4.0 | 0.90 |
Model predictions on new examples
- Let’s examine predictions
| Predicted_target | Age | Total_Bilirubin | Direct_Bilirubin | Alkaline_Phosphotase | Alamine_Aminotransferase | Aspartate_Aminotransferase | Total_Protiens | Albumin | Albumin_and_Globulin_Ratio |
|---|---|---|---|---|---|---|---|---|---|
| No Disease | 19 | 1.4 | 0.8 | 178 | 13 | 26 | 8.0 | 4.6 | 1.30 |
| Disease | 12 | 1.0 | 0.2 | 719 | 157 | 108 | 7.2 | 3.7 | 1.00 |
| Disease | 60 | 5.7 | 2.8 | 214 | 412 | 850 | 7.3 | 3.2 | 0.78 |
| Disease | 42 | 0.5 | 0.1 | 162 | 155 | 108 | 8.1 | 4.0 | 0.90 |
Text classification with a pretrained language model
- We reuse a language model that has already been fine-tuned for positive/negative sentiment classification.
- We do not train it on a new sentiment dataset here.
from transformers import pipeline, AutoModelForTokenClassification, AutoTokenizer
# Sentiment analysis pipeline
analyzer = pipeline("sentiment-analysis", model='distilbert-base-uncased-finetuned-sst-2-english')
analyzer(["I asked my model to predict my future, and it said '404: Life not found.'",
          '''Machine learning is just like cooking—sometimes you follow the recipe,
            and other times you just hope for the best!.'''])
[{'label': 'NEGATIVE', 'score': 0.995707631111145},
{'label': 'POSITIVE', 'score': 0.9994770884513855}]Zero-shot learning
- Now suppose you want to identify the emotion expressed in the text rather than just positive or negative.
- Zero-shot means no labeled training examples for this particular task; the model was still trained on other data.
- Candidate labels and wording affect predictions. We still need to evaluate them.
['im feeling rather rotten so im not very ambitious right now',
 'im updating my blog because i feel shitty',
 'i never make her separate from me because i don t ever want her to feel like i m ashamed with her',
 'i left with my bouquet of red and yellow tulips under my arm feeling slightly more optimistic than when i arrived',
 'i was feeling a little vain when i did this one',
 'i cant walk into a shop anywhere where i do not feel uncomfortable',
 'i felt anger when at the end of a telephone call',
 'i explain why i clung to a relationship with a boy who was in many ways immature and uncommitted despite the excitement i should have been feeling for getting accepted into the masters program at the university of virginia',
 'i like to have the same breathless feeling as a reader eager to see what will happen next',
 'i jest i feel grumpy tired and pre menstrual which i probably am but then again its only been a week and im about as fit as a walrus on vacation for the summer']
Zero-shot learning for emotion detection
from transformers import AutoTokenizer
from transformers import pipeline
import torch

#Load the pretrained model
model_name = "facebook/bart-large-mnli"
classifier = pipeline('zero-shot-classification', model=model_name)
exs = dataset["test"]["text"][10:20]
candidate_labels = ["sadness", "joy", "love","anger", "fear", "surprise"]
outputs = classifier(exs, candidate_labels)
Zero-shot learning for emotion detection
| sequence | labels | scores | |
|---|---|---|---|
| 0 | i don t feel particularly agitated | [surprise, anger, joy, sadness, fear, love] | [0.36008691787719727, 0.3019044101238251, 0.11901266872882843, 0.11381471157073975, 0.060391418635845184, 0.04478989169001579] |
| 1 | i feel beautifully emotional knowing that these women of whom i knew just a handful were holding me and my baba on our journey | [joy, love, surprise, fear, sadness, anger] | [0.3699439465999603, 0.2887146472930908, 0.2560795247554779, 0.04292328655719757, 0.033448830246925354, 0.008889724500477314] |
| 2 | i pay attention it deepens into a feeling of being invaded and helpless | [fear, surprise, sadness, anger, joy, love] | [0.34146833419799805, 0.3088077902793884, 0.25616905093193054, 0.07989828288555145, 0.007844817824661732, 0.0058116912841796875] |
| 3 | i just feel extremely comfortable with the group of people that i dont even need to hide myself | [joy, surprise, love, sadness, anger, fear] | [0.33052223920822144, 0.2947238087654114, 0.15343129634857178, 0.07691426575183868, 0.0759672224521637, 0.06844119727611542] |
| 4 | i find myself in the odd position of feeling supportive of | [surprise, joy, fear, love, sadness, anger] | [0.828799307346344, 0.043179288506507874, 0.03977357596158981, 0.03141310438513756, 0.03141240030527115, 0.02542232535779476] |
| 5 | i was feeling as heartbroken as im sure katniss was | [sadness, surprise, fear, love, anger, joy] | [0.7667986154556274, 0.1818457394838333, 0.02587115205824375, 0.011756801046431065, 0.008171561174094677, 0.005556143820285797] |
| 6 | i feel a little mellow today | [surprise, joy, love, fear, sadness, anger] | [0.49373677372932434, 0.2632191479206085, 0.11367887258529663, 0.06402125954627991, 0.05095506086945534, 0.01438884437084198] |
| 7 | i feel like my only role now would be to tear your sails with my pessimism and discontent | [sadness, anger, surprise, fear, joy, love] | [0.6992812752723694, 0.20048636198043823, 0.061858512461185455, 0.03287411853671074, 0.003646855941042304, 0.0018528379732742906] |
| 8 | i feel just bcoz a fight we get mad to each other n u wanna make a publicity n let the world knows about our fight | [anger, surprise, sadness, fear, joy, love] | [0.6029902696609497, 0.19827169179916382, 0.10198825597763062, 0.08116933703422546, 0.01011710800230503, 0.00546331238001585] |
| 9 | i feel like reds and purples are just so rich and kind of perfect | [joy, surprise, love, anger, fear, sadness] | [0.36441531777381897, 0.30512040853500366, 0.1946246474981308, 0.05556635558605194, 0.05413525179028511, 0.026138003915548325] |
Optional: How the food clusters were computed
The main demo groups neural-network representations with K-Means.
The representation determines which similarities the clustering method can find.
Activity 2
Think of a problem you have come across in the past which could be solved using machine learning.
- What would be the input and output?
- How do humans solve this now? Are there heuristics or rules?
- What kind of data do you have or could you collect?
- What mistakes could the system make, and who would be affected?
- Should ML support a person or make the final decision?
Ways of learning from data
- Supervised learning: predict targets from labeled examples
- Unsupervised learning: discover structure without supplied targets
- Reinforcement learning: learn actions through interaction and rewards
- Generative AI: generate content; models can use several learning approaches
- Recommendation systems: learn preferences, often combining multiple approaches
These categories are not mutually exclusive.